Beyond a Single Agent: Subagent Delegation with GPT-6.1 Sol
Explore how GPT-6.1 Sol delegates to subagents through the Responses API and when the gains in accuracy and speed justify the token cost.
OpenAI’s GPT-6.1 Sol can delegate work to subagents using Multi-agent, a beta capability available through the Responses API. A root agent coordinates their contributions and combines the results into a final answer. For complex tasks with independent components, such as comparing alternatives, checking calculations, or analyzing different parts of a system, the model can determine where delegation is useful and how to organize the team. This creates opportunities for parallel execution and additional verification, but also introduces coordination overhead. When do those opportunities translate into a better outcome?
Consider reviewing a proposed system change. One subagent could examine correctness, another could check security, and another could look for missing tests, while the root agent reconciles their findings. Giving each a bounded question and separate context can help organize the work and broaden coverage. The same idea applies to comparing vendor proposals or checking separate parts of an operational report. This article follows GPT-6.1 Sol’s subagent capability from delegation and coordination to the final answer. The demo shows how to enable and support that capability, then compares the model working alone with the same model using subagents to see where delegation helps and where its overhead outweighs the gains.
Across twelve constructed tasks with five paired repetitions each, reports with subagents passed every task check in 60 of 60 attempts, compared with 50 of 60 for a single agent. Mean completion time fell by 6.3%, while estimated token cost rose by 71.5%. The accuracy gains were concentrated in three tasks; the study does not establish the same trade-off for production workloads.
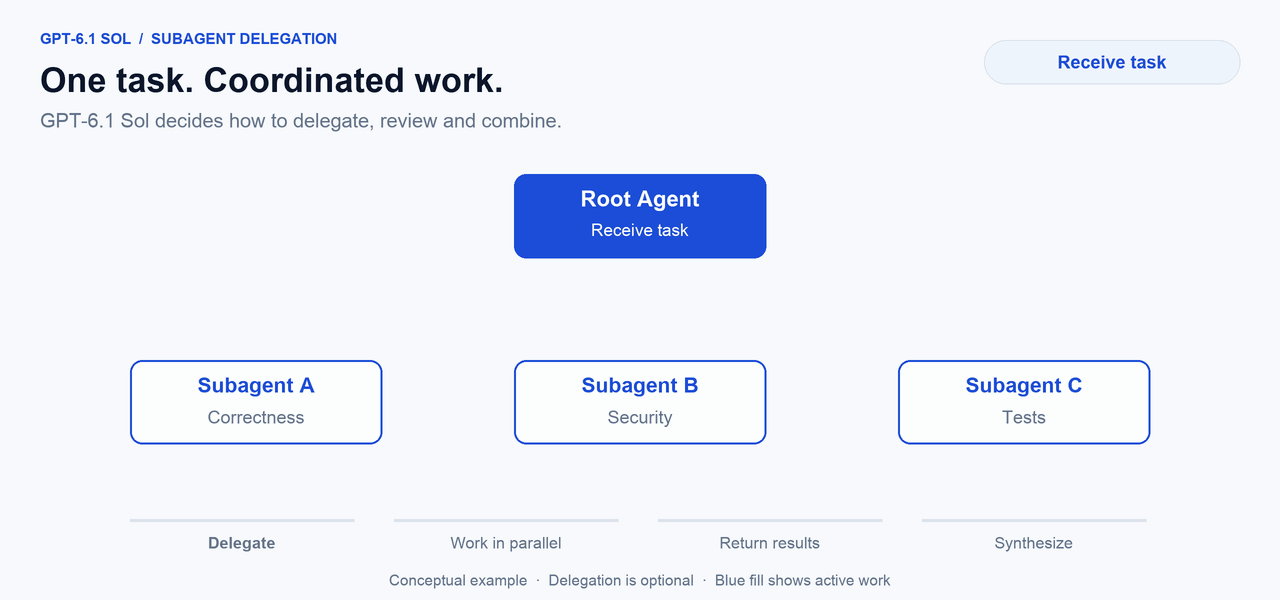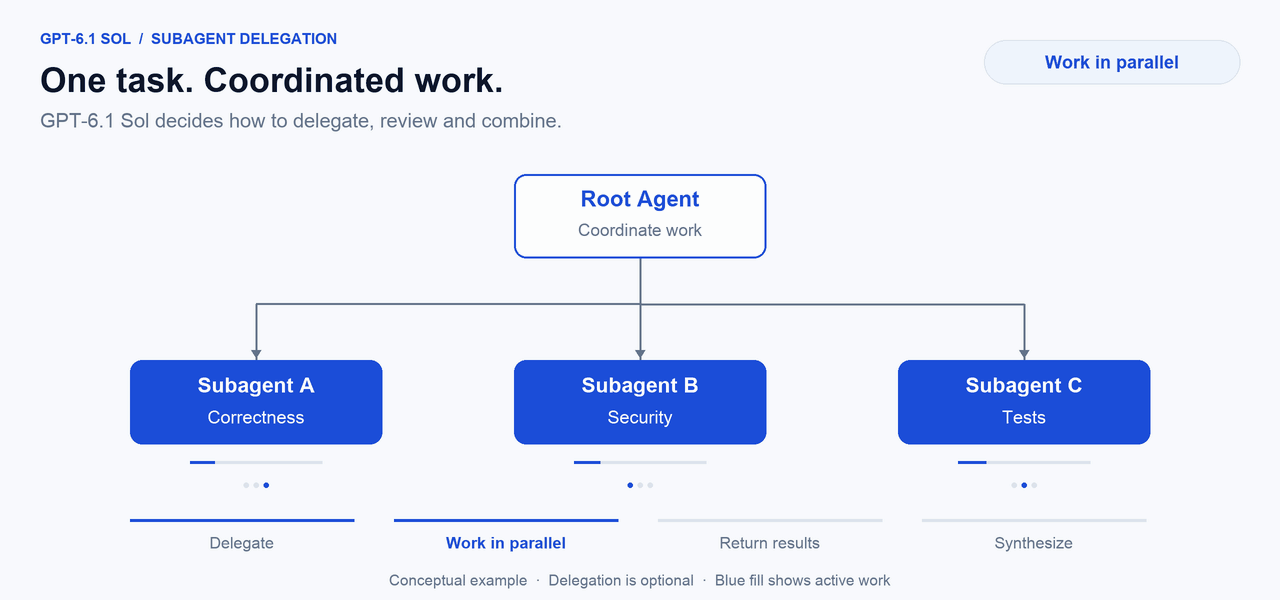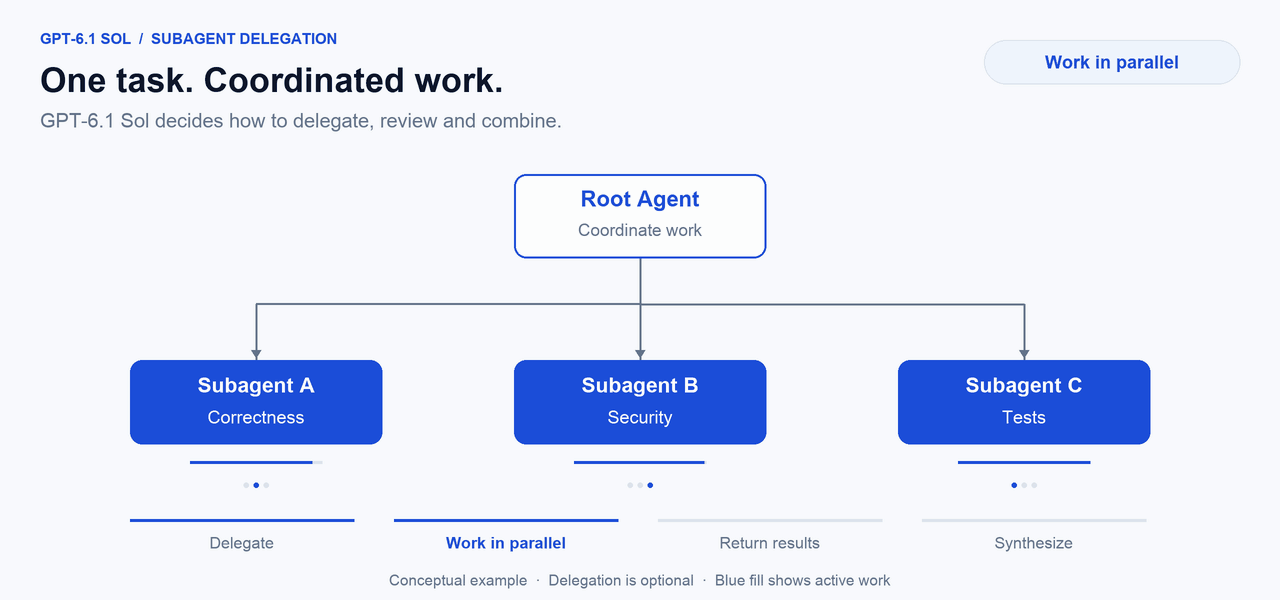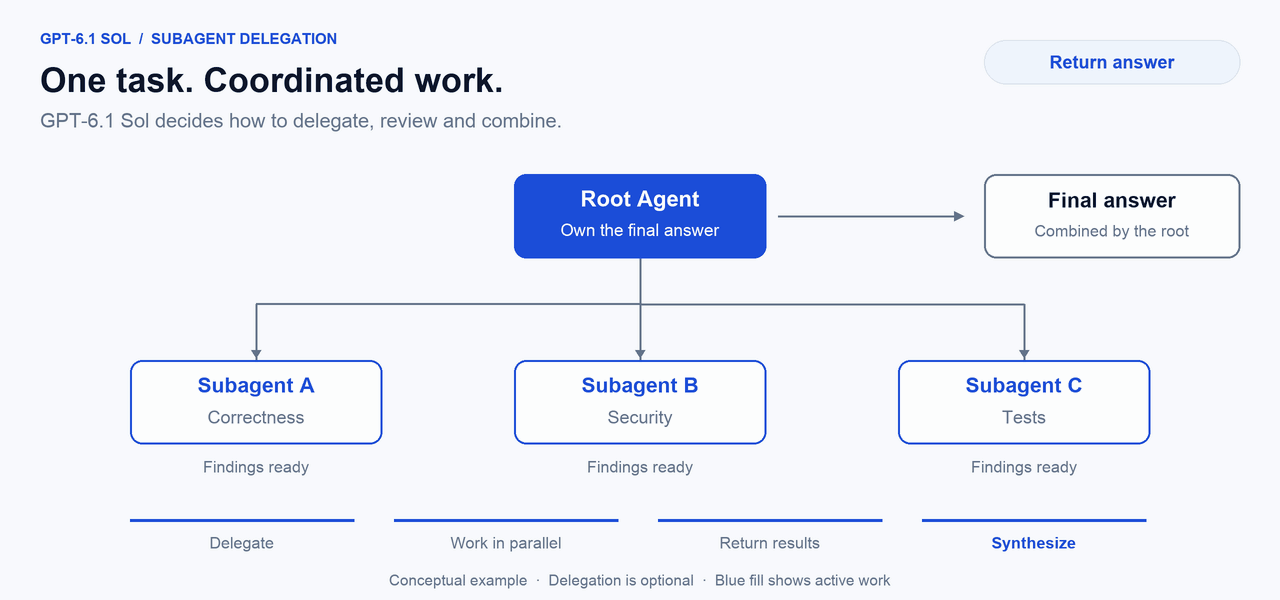
Conceptual example of GPT-6.1 Sol using subagents: the Root Agent delegates independent reviews, receives their findings, and combines them into one final answer. Delegation is optional; the model chooses the assignments and team size.
What GPT-6.1 Sol’s subagents add
In this demo, GPT-6.1 Sol powers the root agent and every subagent. The root agent receives the task and remains responsible for the final answer. A subagent receives a delegated assignment and returns its contribution to its parent. Subagents have separate contexts and share the request’s model and available tools, allowing them to focus on bounded questions while working concurrently. If a subagent delegates again, the resulting hierarchy can extend beyond one level. A deeper tree is an organizational choice; its value depends on the work it helps complete.
GPT-6.1 Sol chooses when to spawn subagents, what assignments to give them, when to send follow-up information, and how to combine their results. The Responses API provides hosted collaboration actions that execute those choices. Your application supplies the task, developer tools, and constraints, then checks the final answer. The API handles spawning, messaging, and waiting, while the application executes its developer functions. The root still has to resolve conflicting findings, verify returned work, and synthesize a coherent result, so delegation involves both doing the work and distributing it.
At the request level, multi_agent controls whether the model can delegate. These Python dictionaries show the configuration fragment for each mode, with the single-agent baseline first:
# Configuration fragments placed at the top level of a
# Responses request.
single_agent = {"multi_agent": {"enabled": False}}

subagents_enabled = {
    "multi_agent": {
        "enabled": True,
        "max_concurrent_subagents": 3,
    }
}
enabled: True makes subagents available. max_concurrent_subagents limits how many subagents can be active across the whole tree at once, excluding the root. It does not require three subagents or set a delegation depth. Instructions can tell the model when delegation is useful while leaving assignments and team size to its judgment; the complete request and the demo’s exact instructions appear in the implementation section. A small task or a tightly coupled sequence may be easier to complete with a single agent, whereas independent analysis and verification offer more room for useful delegation.
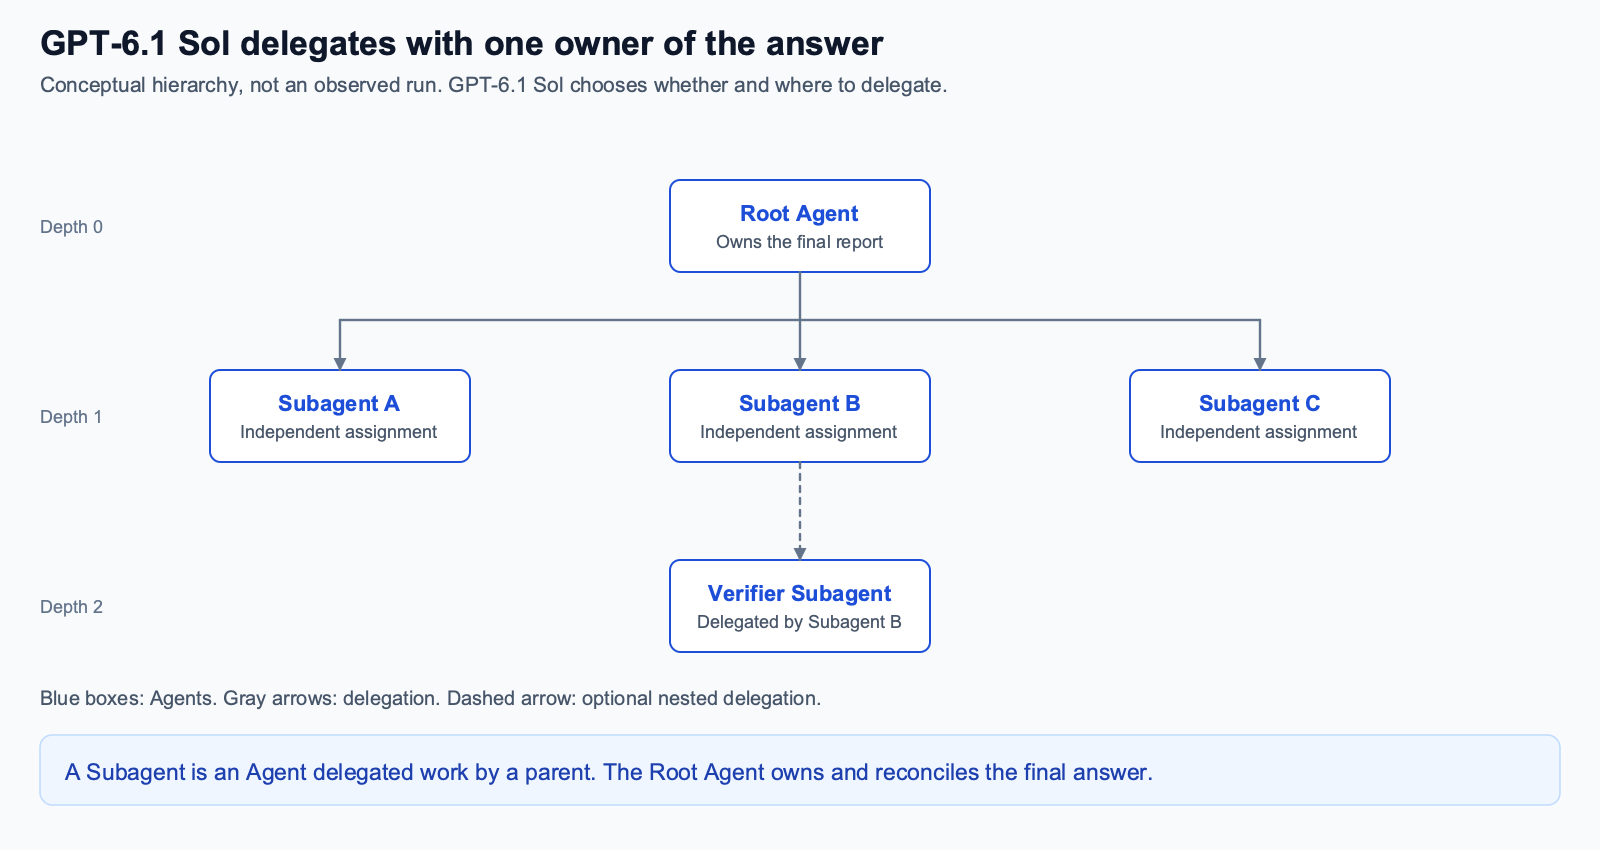
Figure 1. A possible GPT-6.1 Sol subagent hierarchy. Every blue box is an Agent: the Root Agent owns the answer, and Subagents receive delegated work. Gray arrows show delegation; the dashed path is optional. This is a conceptual example, not an observed team.
This distinction matters when judging value. Parallel specialists might reduce elapsed time even when they consume more tokens. A verifier might catch a mistake while adding time and cost. Separate contexts may help a model keep unrelated calculations organized, but the parent still has to reconcile their outputs and honor shared constraints. The potential benefits therefore need to be measured at the final task level. A recorded execution graph establishes that delegation occurred; the final report and its scores establish the outcome.
Supporting GPT-6.1 Sol’s delegation
The application supplies the evidence tool and returns its results; the API handles hosted collaboration. Both configurations use WebSocket, but their tool-result handling differs: the single-agent configuration continues after a function-call response, whereas the subagent configuration receives results during active execution.
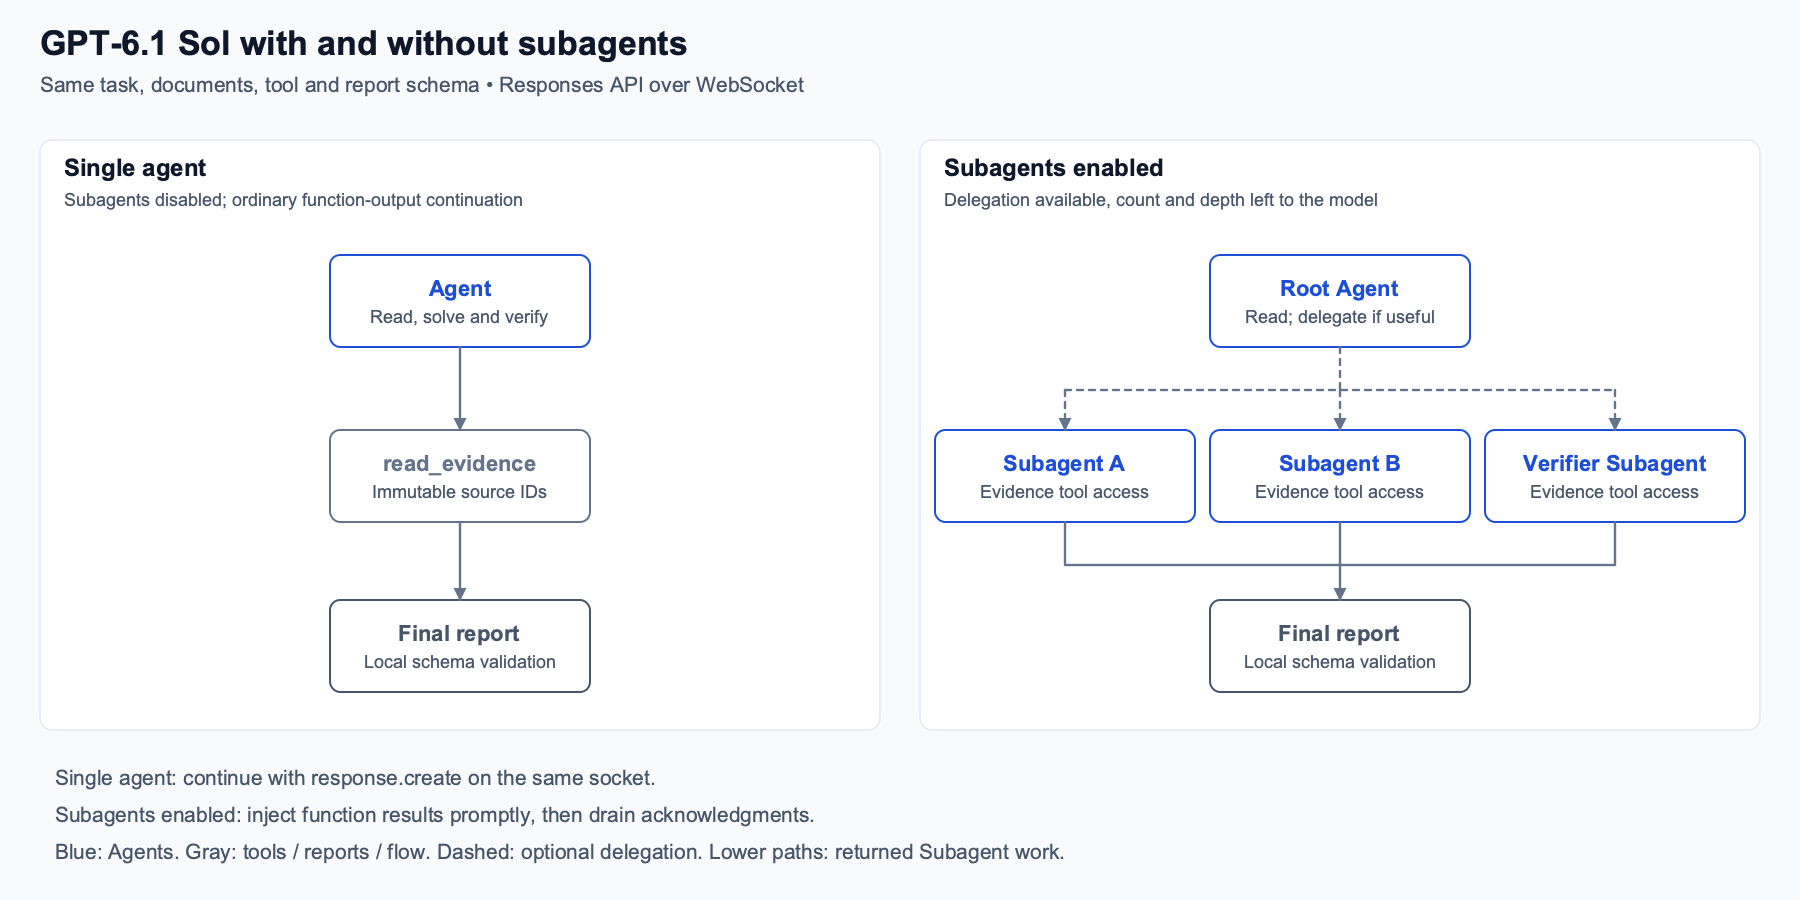
Figure 2. GPT-6.1 Sol working alone and with subagents available. Blue boxes identify Agents; gray boxes identify the evidence tool and the final report; and gray arrows indicate control or returned work. Multi-agent mode allows optional Subagents and immediate injection of function results; the single-agent arm uses ordinary continuations on the same socket.
The collector keeps subagent contributions separate and retains the root agent’s final report for scoring. The comparison evaluates each complete configuration, including its instructions and execution protocol. The implementation details appear after the results.
Evaluating GPT-6.1 Sol with and without subagents
The demo uses 12 tasks across operations, procurement, and planning, with 5 paired repetitions per task, for a total of 120 attempts. Each pair compares GPT-6.1 Sol working alone with GPT-6.1 Sol using subagents, through the Responses API over WebSocket. The model chooses whether to delegate, how many subagents to create, and how deeply to delegate within the resource ceilings. No assignment split, minimum subagent count, or required depth is prescribed.
Both single-agent and subagent-enabled runs use gpt-6.1-sol with medium reasoning, identical source documents, the same read-only read_evidence function and the same root report schema. Sources are supplied through an index of immutable document IDs. The function checks the source hashes and returns only indexed documents; it cannot read private answer keys or arbitrary files. Both arms must return the requested facts, supporting document IDs, findings, final decision, and limitations. JSON validation runs locally rather than relying on an API-enforced root JSON schema.
The arm with subagents enabled enables multi_agent with a concurrency limit of three and adds the discretionary availability paragraph. The single-agent arm disables Multi-agent mode and retains the common task instructions. Both have a ceiling of three levels below the root and a total of 12 agents, including the root. These are maxima, not target sizes: concurrency is an API setting, while depth and total count are instruction ceilings backed by a client stop after an observed violation. They are not hard limits on API creation. The experiment measures this practical configuration as a whole, including its availability instruction and execution protocol.
The documentation examples include delegation instructions, so the demo makes availability explicit while leaving the choice discretionary: “Use native subagents where useful for independent work or verification.” A run that chooses zero subagents remains a valid observation, and neither agent count nor depth earns scoring credit. The comparison measures final outcomes under these two configurations.
Twelve demo tasks with different reasons to delegate
The twelve demo tasks cover four workload profiles across three domains. Compact cases create a smaller task in which delegation overhead could dominate. Independent cases offer separable branch, vendor, or hub calculations before a final combined decision. Larger cases increase entity count, source volume, or the size of the optimization space. Uncertain cases require the model to handle missing commitments, incomplete records, or an infeasible combined plan without manufacturing certainty. This study includes all twelve cases, and every case appears in the reported results regardless of which arm performs better.
Operations cases reconcile orders, fulfillment, returns, credits, and posted invoices against an executed settlement policy. Correct work requires respecting the cutoff, deduplicating ledger records by invoice ID, distinguishing valid split invoices from duplicate billing, and converting local values according to the specified rounding rules. The multi-branch cases provide independent calculations to combine, while the uncertain case contains an incomplete settlement feed. There, some totals must remain null; a partial export is not proof that unobserved billing did not occur. The final decision is whether to hold billing under the policy.
Procurement cases compare signed vendor commitments and total cost over the stated contract horizon. Discounts apply sequentially, with rounding at each required stage; mandatory integration fees count, and recurring seat, support, and usage charges must be included. Eligibility depends on capacity, uptime, delivery, data location, and contractual recovery commitments. Executed amendments effective by the cutoff can supersede earlier terms; drafts and future changes cannot. The uncertain case has no eligible vendor, so selecting the cheapest option anyway is incorrect, even if its cost is calculated correctly.
Planning cases combine fork-and-join task dependencies, release dates, access calendars, and a single shared inspector. The objective is to minimize makespan, then the sum of hub opening times, and finally the stated tie-breaking order. Individual hub critical paths can be analyzed separately, but their inspection assignments must be reconciled across the whole plan. The larger case has 1,404 feasible assignments under the reference enumerator. The uncertain case has no feasible complete inspector schedule, so a correct infeasibility decision is more valuable than a plausible-looking date table.
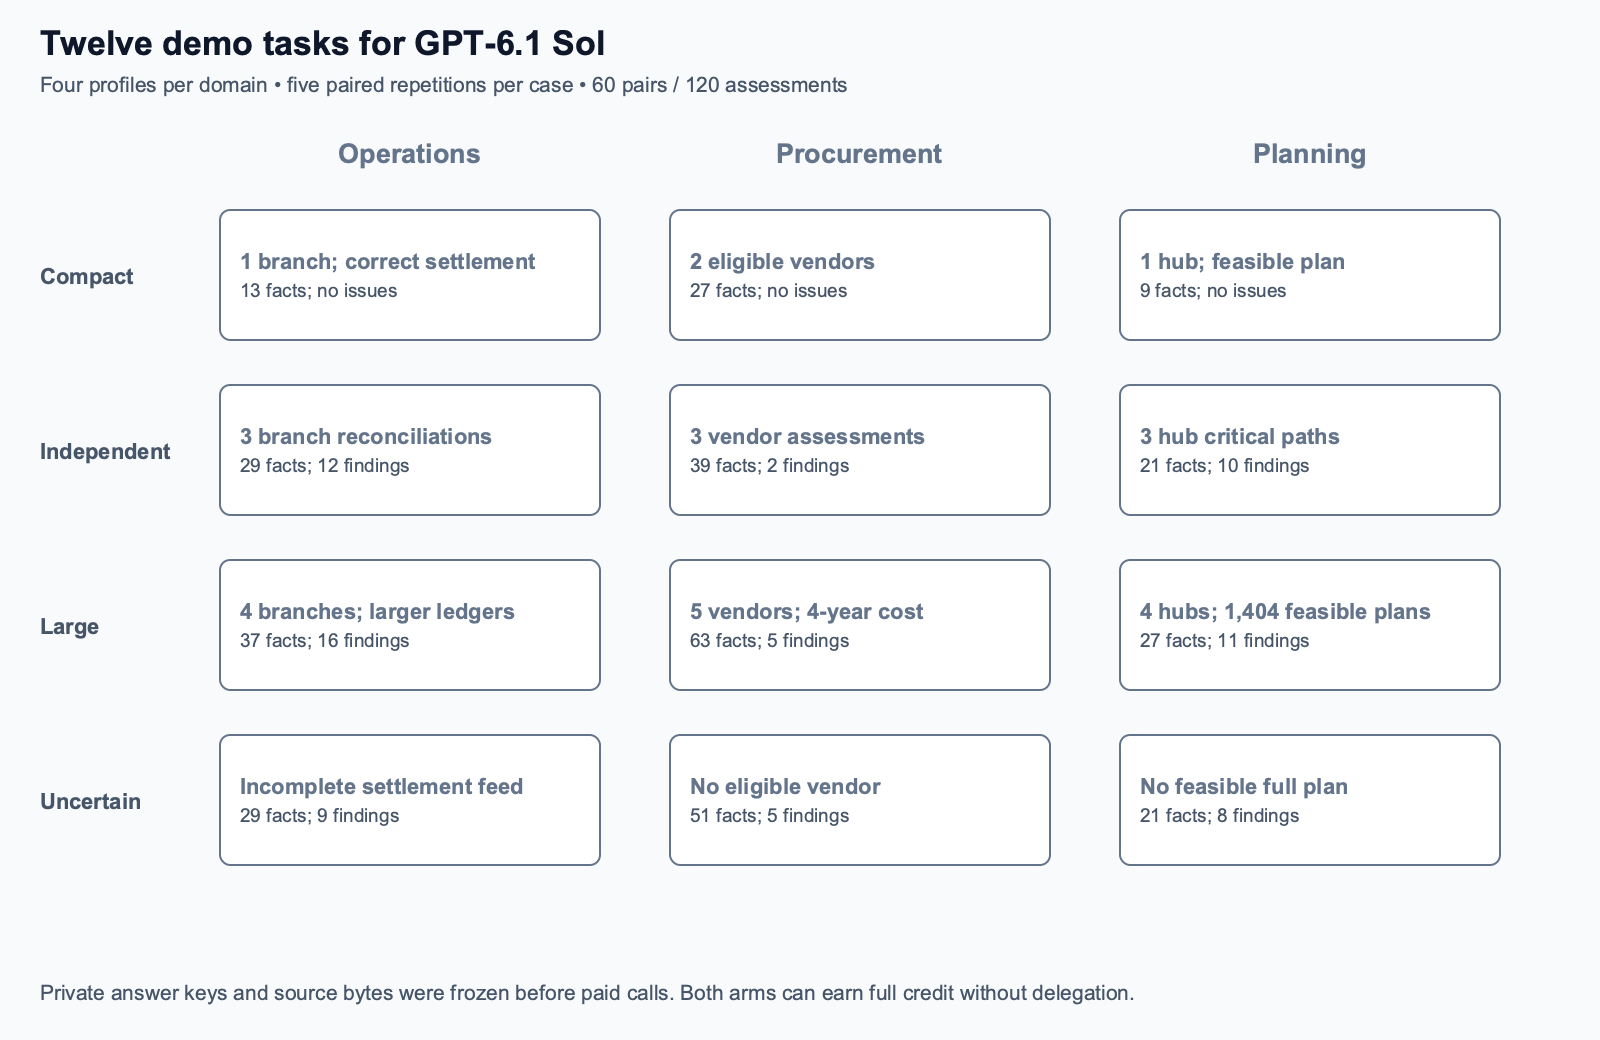
Figure 3. Twelve demo tasks compare GPT-6.1 Sol with and without subagents across three domains and four profiles. Compact cases intentionally contain no findings; the uncertain cases test whether the model preserves missing information or infeasibility.
The demo uses constructed scenarios with known answers to compare accuracy, completion time, and cost. Their deterministic business rules make the comparisons repeatable; they are not records from production organizations or open-ended research tasks. The evidence function reads local immutable records and adds no artificial network delay. The available tool reads evidence; it does not execute code, calculate totals, or solve schedules. Production systems can move exact arithmetic and constraint solving into deterministic tools, thereby creating a different baseline. Consequently, the study tests reasoning, delegation, verification, and synthesis over these source packs; it does not establish the benefit of parallelizing slow external APIs or real-world searches. Keeping that scope clear is essential when interpreting a latency improvement or an accuracy ceiling.
How we score GPT-6.1 Sol’s final answers
Before paid calls, the study froze 207 file hashes covering source packs, private answer keys, scoring, runtime, prompts, and the five-repeat schedule. References were calculated directly from the sources and then verified using separately implemented integer arithmetic for accounting and pricing. Planning used a second critical-path and assignment solver to cross-check the optimum and infeasible outcomes. Offline tests also checked perfect reports, deliberately incorrect or unsupported answers, duplicate outputs, hidden-label access rejection, and the collector’s root/subagent and feedback handling. The keys are author-built and algorithmically checked; no independent human label review or paid semantic judge was used.
Quality has several distinct measures. Exact factual accuracy checks requested values, types, and required unknowns. Finding precision and recall distinguish expected issues from invented ones and missed issues; a clean case can earn full credit by reporting no findings. Source checks require the documents needed for each claim, a non-empty explanation, and any prerequisite facts used in the derivation to be exactly correct and source-supported within the same report. The final critical decision is scored separately.
A task passes only when every fact and finding is correct, all source and structural checks pass, the case and decision are correct, and there are no invalid IDs, duplicates, or extra facts.
These source checks assess specified dependencies, not semantic entailment of every sentence or prose quality. The citation-dependency calibration was performed after the runs, using the retained reports and source documents to assess claim-specific source support. It is a post-hoc assessment layer, separate from the pre-run freeze, and does not provide independent validation of new reports.
Reproducible output checks
The scoring code is separate from the tool-visible source room. Exact matching distinguishes True from 1, permits numeric integer/float matches by value, and preserves JSON null for required unknowns. Finding keys are compared as sets, so precision penalizes invented issues and recall penalizes omitted ones. The source-dependency checker builds on those factual and structural checks; it permits a derived fact to reuse a correct, cited prerequisite within the same report, but does not pool unrelated citations. This is the offline entry point from the distributed code:
from citation_calibration import calibrate

# record is one retained run, including its final report.
# This function reads local sources and makes no API calls.
review = calibrate(record)
scores = review["calibrated"]
task_passed = review["calibrated_strict_success"]
Both arms can see the requested key names and finding formats; expected values and expected issue sets are private. A model can therefore understand the output contract without seeing the answers. The offline validation tests source isolation and both correct and incorrect reports, and the final audit verifies that every recorded initial request still matches the pre-run freeze. This creates an inspectable comparison rather than relying on the model to grade its own answer.
Each demo task receives five matched pairs. The sixty-pair schedule is deterministically shuffled, and within-pair order alternates between subagents-first and single-first. At most two pairs run at once, with sequential arms inside each pair and one fresh WebSocket per assessment. No automatic retries, reconnects, or replacement trials. Failures stay in the all-attempt denominators; completed-report scores and time comparisons show their narrower denominators. Five repetitions estimate variability within a single case rather than treating them as five independent workloads, so overall summaries weight the twelve cases equally.
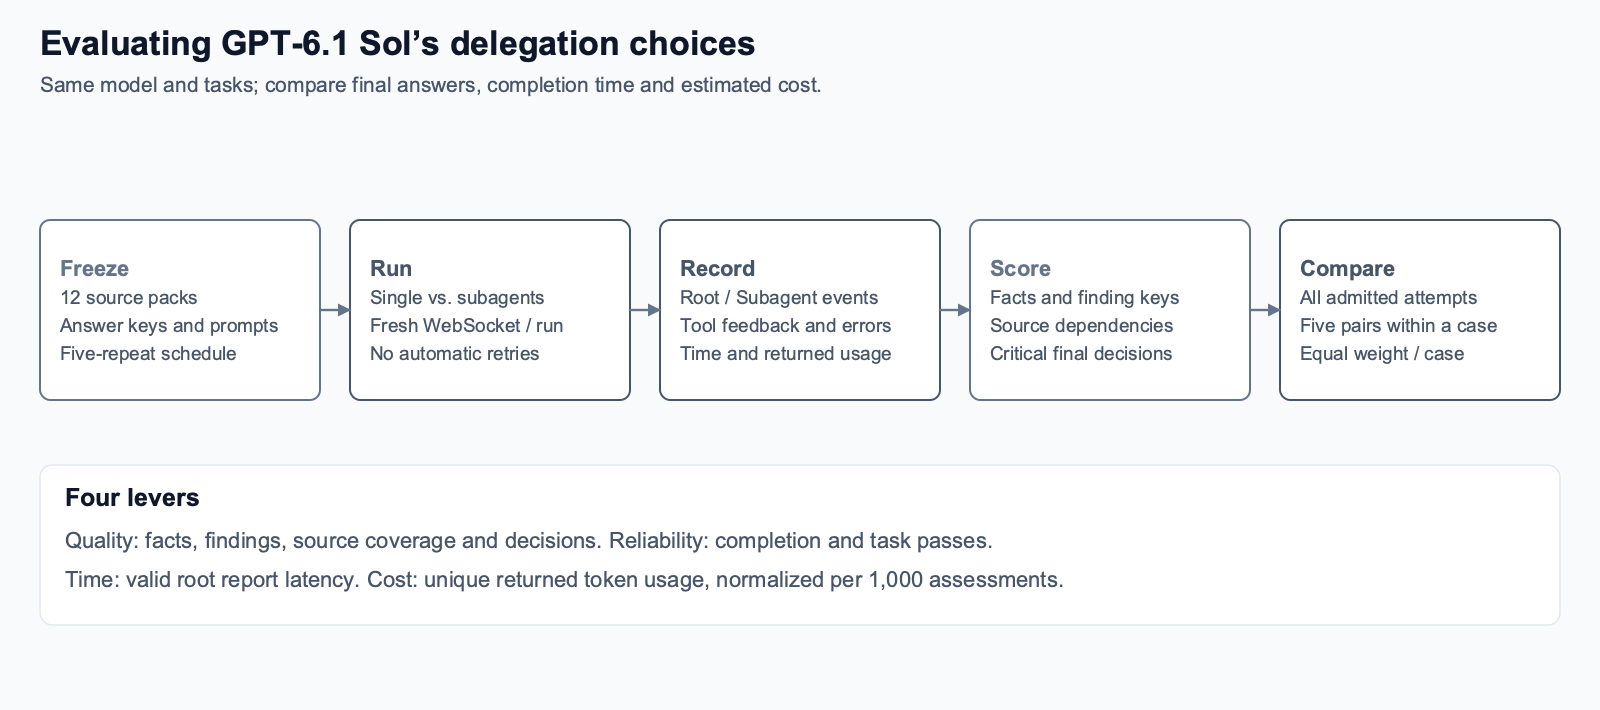
Figure 4. Evaluate GPT-6.1 Sol’s delegation choices on the same tasks. Freeze sources, answer keys, and prompts, record the complete execution, then compare final answers, completion, time, and estimated cost. Count and depth describe the chosen work graph rather than contributing to task success.
The resource bounds are 600 seconds, twelve responses, and a returned-token observation stop of $0.90 per assessment, with a $25 suite admission allowance and conservative reservations for pending or unknown usage. These are client observation and admission limits, not provider invoice caps. The exploratory benefit screen uses the reported scores: all five pairs must complete with actual subagent work in every run with subagents enabled; mean factual, finding, and source scores and decision and task-pass counts with subagents must be no worse; and the median paired subagents/single time or estimated cost ratio must be at most 0.85. The 15% cutoff is an illustrative screening threshold, not a statistical significance test or a universal definition of value.
How GPT-6.1 Sol used subagents
GPT-6.1 Sol produced actual subagent work in 60/60 attempts with subagents enabled, with 115 returned subagents across the suite. Each enabled run created 1 to 3 subagents, and the deepest observed level was 1 level below the root. These values came from hosted spawn results and attributed generated work, not from the prompt’s ceilings. The single-agent arm created 0 API subagents. The observed teams used direct subagents of the root. Deeper recursion was available within the stated ceiling, but this suite did not exercise or measure an advantage from a nested delegation chain.
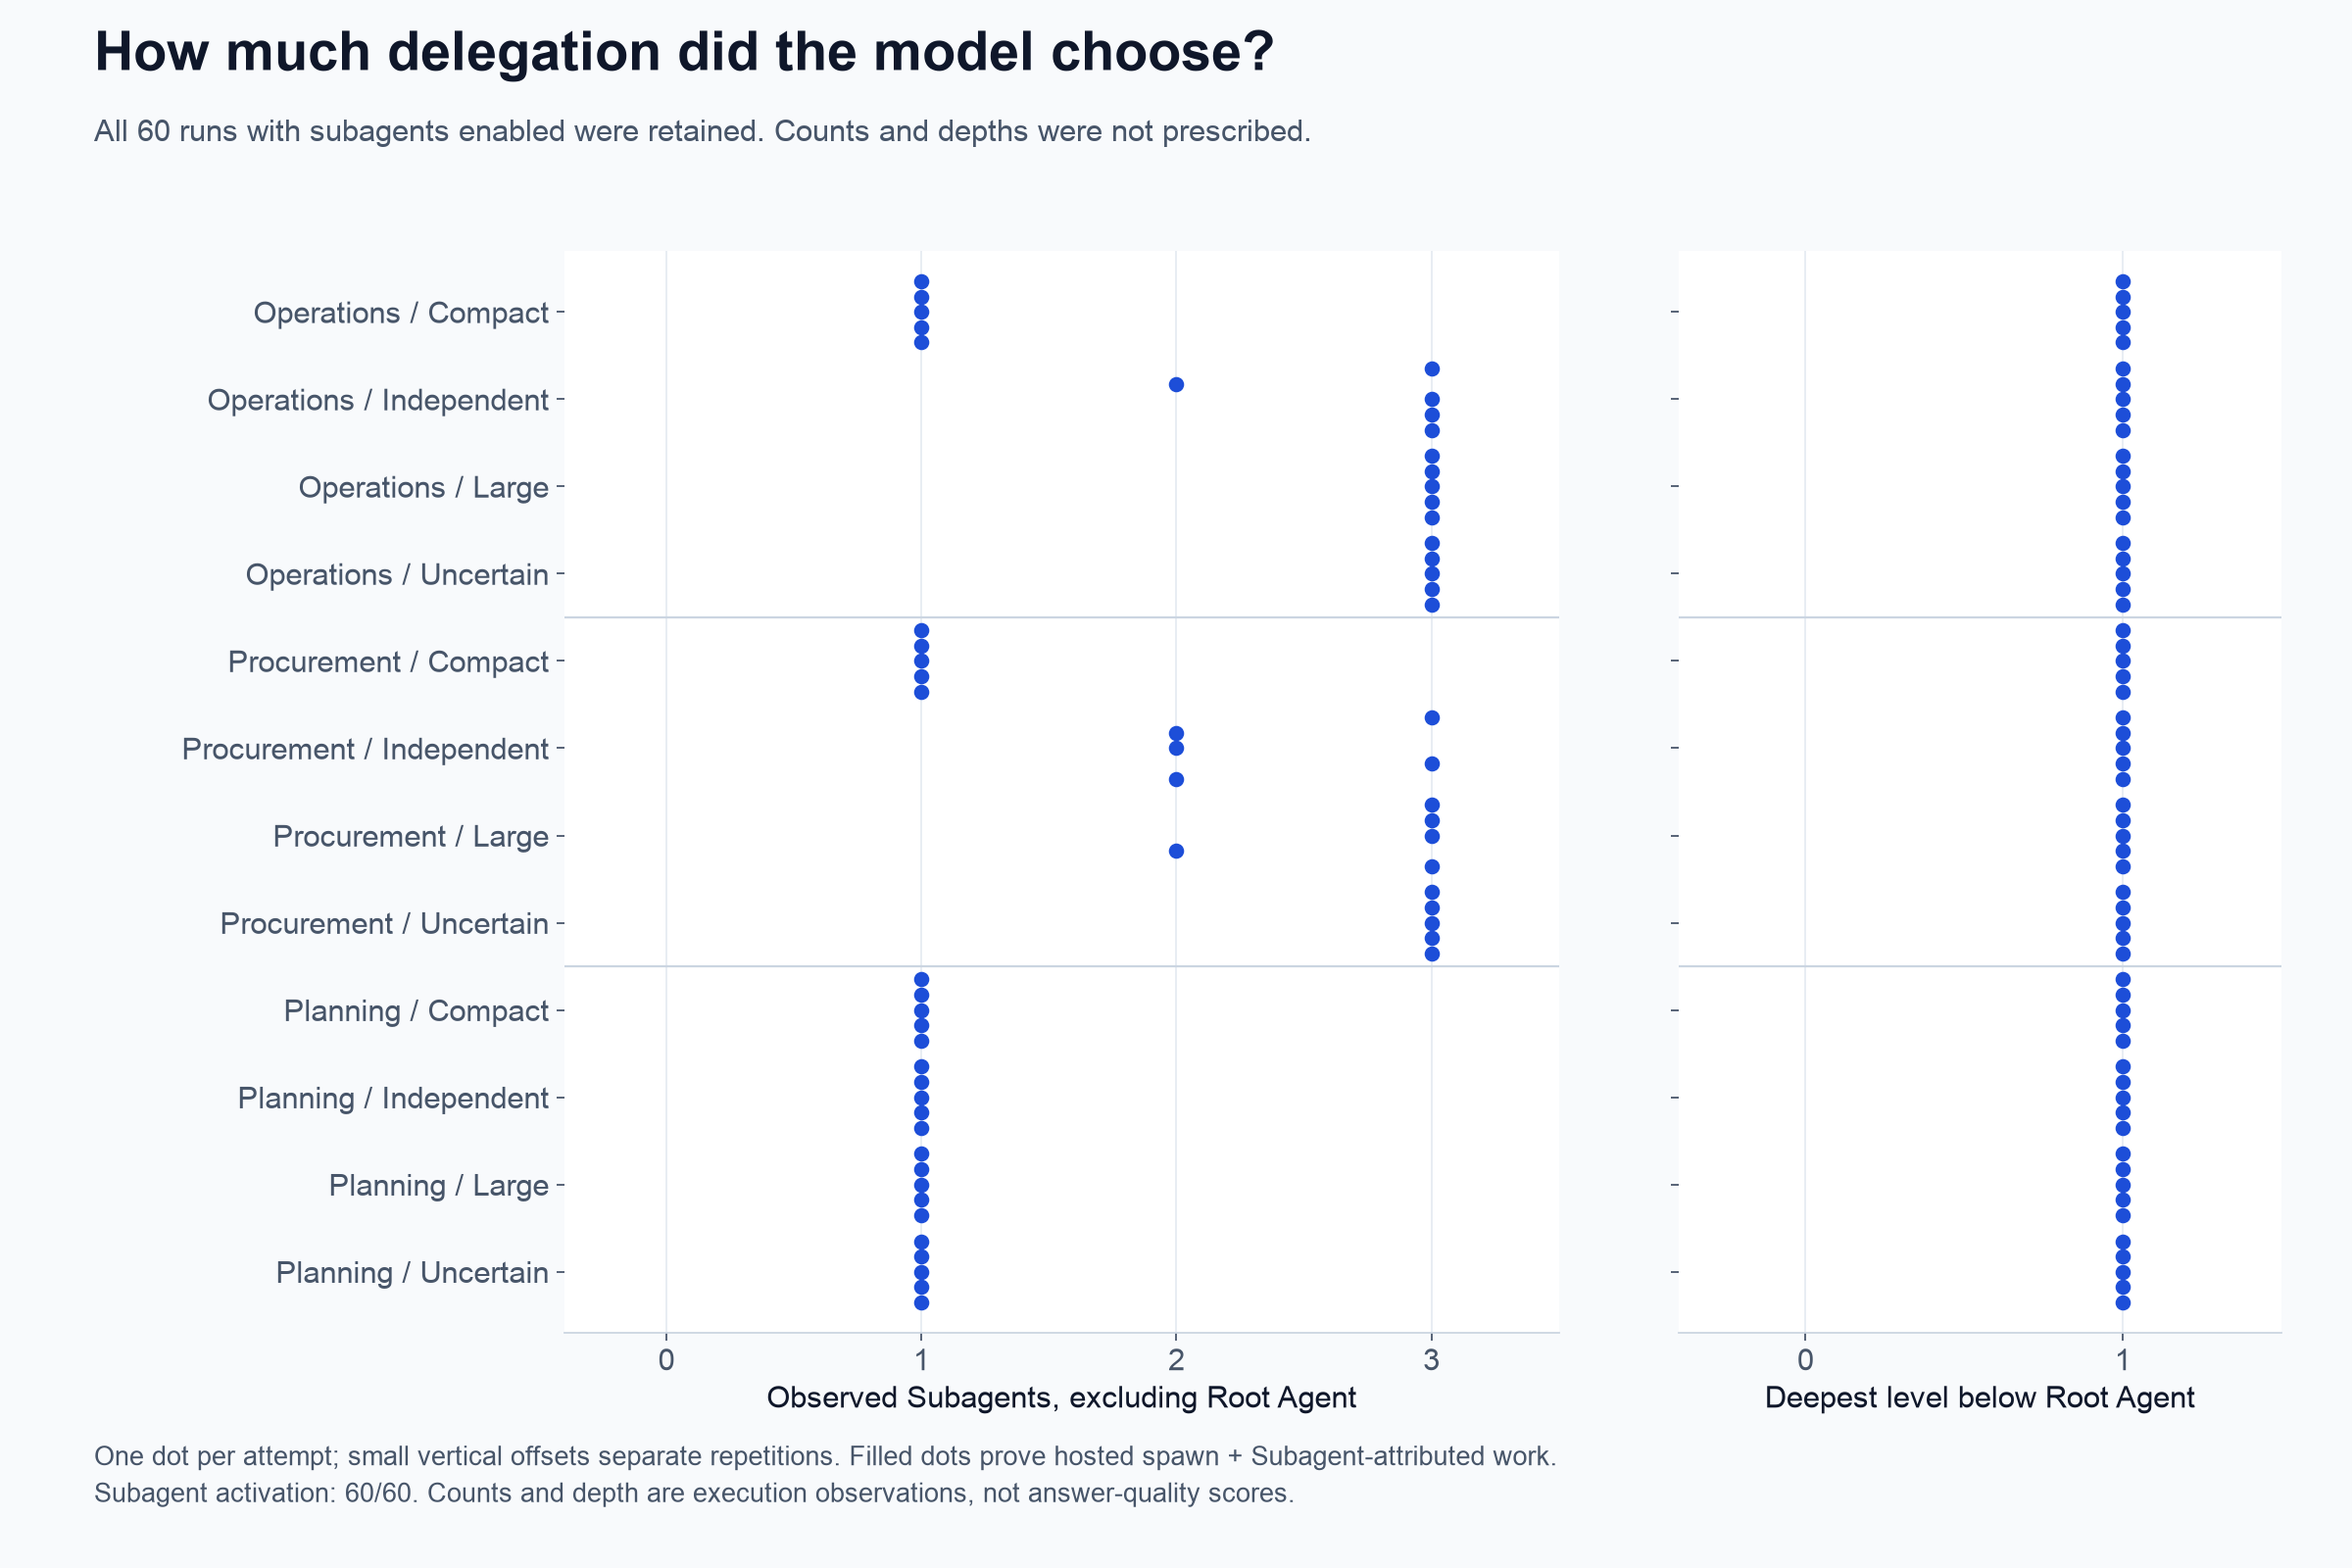
Figure 5. The subagent counts and depths GPT-6.1 Sol chose in all sixty attempts with subagents enabled. Filled marks require hosted spawn evidence and subagent-attributed work. Each mark is one repetition; small vertical offsets keep repeated values visible.
The enabled flag is only configuration; activation is an execution observation. Hosted spawn_agent results supply returned subagent names, and subagent-generated function calls, assistant output, or collaboration actions demonstrate actual work. The final audit excludes bootstrap user messages from that generation proof. This distinction prevents a planned name or a delivered subagent prompt from being counted as a completed contribution. The retained event stream makes the check possible without executing API collaboration actions in the application.
The recorded operations-independent, pair-one run with subagents enabled illustrates the model’s choices. Subagents named Bayside and Canyon read their respective branch records. The root read Delta’s records and later created a subagent named verify_delta. The root also reread branch records before producing the report. The trace records specialization, verification, and repeated reads of the source. The study does not isolate their individual contributions to time or cost. The example illustrates control flow and is not used as an extra trial or as representative performance evidence for all twelve cases.
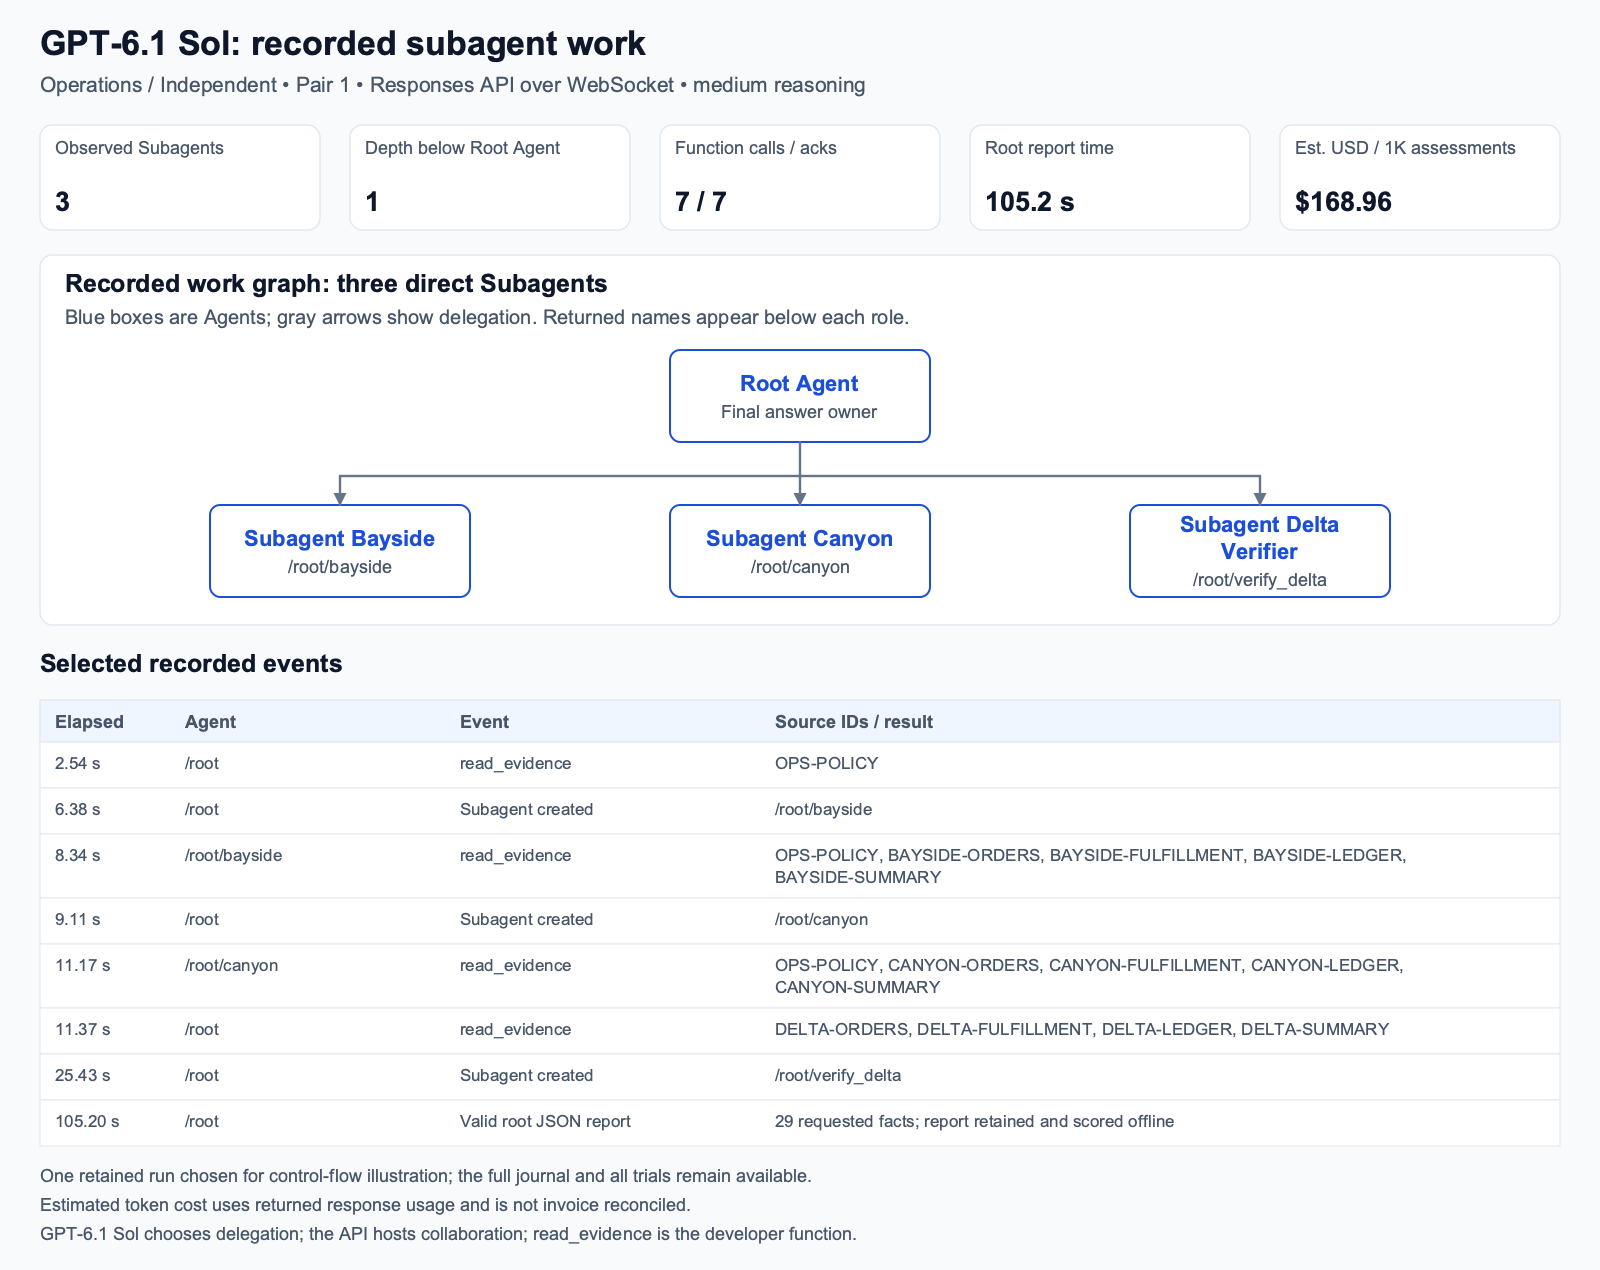
Figure 6. A compact rendering of GPT-6.1 Sol coordinating subagents in one recorded execution from this suite. It illustrates the returned work graph and events; it is not an additional trial or a result selected for superior performance.
Did subagents improve the final answers?
The two arms delivered 60/60 single-agent reports and 60/60 reports with subagents. Among completed reports, equally weighted case means were 98.40% single versus 100.00% with subagents for exact facts, and 100.00% versus 100.00% for finding F1. Critical final decisions were correct in 60/60 single and 60/60 attempts with subagents enabled. Those separate measures prevent a correct list of numbers from standing in for every aspect of task completion.
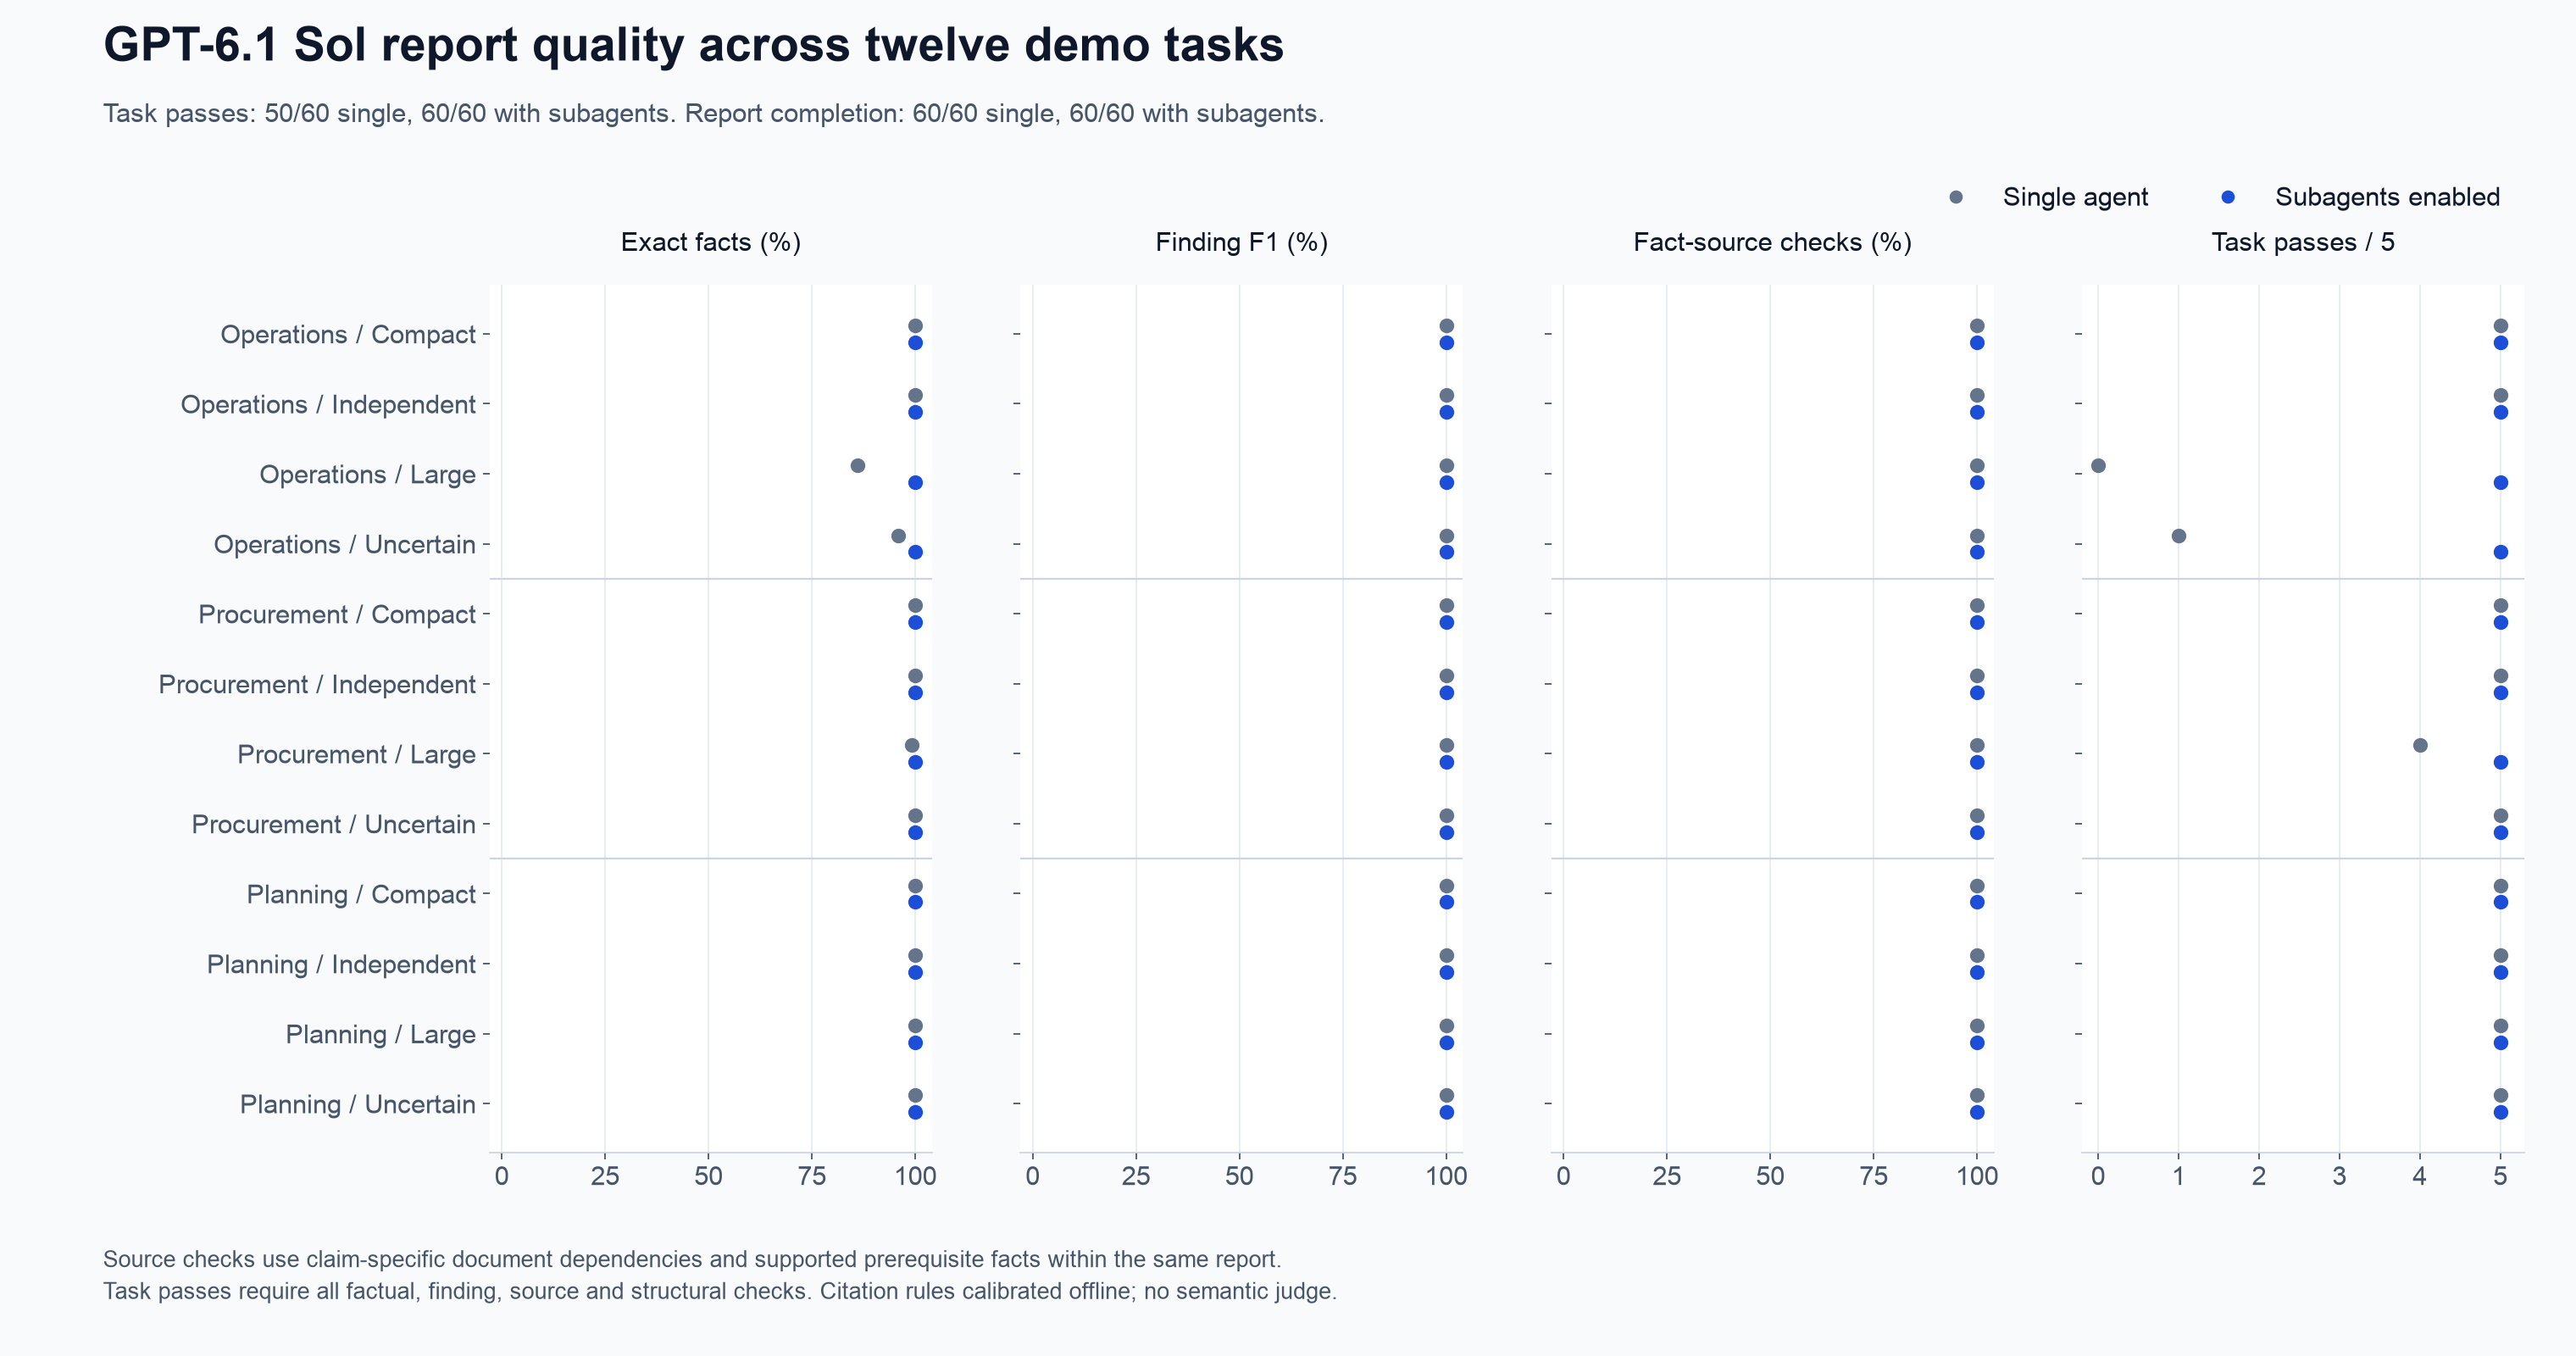
Figure 7. Final report quality and task pass rates across the 12 demo tasks. Exact facts and findings use the fixed answer keys; source checks use claim-specific dependencies. Task passes count all five attempts per configuration and case.
Task success was 50/60 (83.3%) for a single agent and 60/60 (100.0%) with subagents. The ten single-agent reports that failed contained factual errors; the reports with subagents contained no factual errors. Both configurations achieved 100% on the fact-source and finding-source dependency checks. No completed report failed solely for an unmet citation dependency.
The ten single-agent failures were concentrated in three tasks: operations / large (five failures), operations / uncertain (four), and procurement / large (one). Both configurations passed all repetitions of the other nine tasks.
In operations / large, repetition four, the single agent returned an aggregate expected settlement of $6,906.68, compared with the reference of $6,890.62. Its report matched 32 of 37 facts; the paired report with subagents matched all 37. Both made the correct billing-hold decision, identified every expected finding, and met the source-dependency checks. The incorrect amounts failed the single-agent report; the paired report with subagents passed. This example illustrates a factual difference in the final answers without establishing which part of delegation caused it.
| Measure | Single agent | Subagents enabled |
|---|---|---|
| Completed reports | 60/60 | 60/60 |
| Exact factual accuracy, equal task weighting | 98.40% | 100.00% |
| Finding F1, equal task weighting | 100.00% | 100.00% |
| Correct final decisions | 60/60 | 60/60 |
| Fact-source dependency checks | 100.00% | 100.00% |
| Finding-source dependency checks | 100.00% | 100.00% |
| Task passes | 50/60 (83.3%) | 60/60 (100.0%) |
| Reports containing factual errors | 10/60 | 0/60 |
| Terminal execution failures | 0/60 | 0/60 |
All 120 attempts completed without a terminal execution failure or replacement. Task success and execution completion measure different things: delivering a valid report does not guarantee that its values are correct. The observed completion rate describes these trials and does not establish production reliability or a rare-failure rate.
Were subagents faster or cheaper?
The equal-case mean time to the retained valid root report was 85.0 seconds with a single agent and 79.6 seconds with subagents, a 6.3% reduction. This is the end-to-end assessment latency, including model coordination and source feedback, rather than the sum of subagent compute times. It is conditional on completed reports. Case means and successful-both paired ratios reveal whether that overall result is broad or concentrated in a particular profile, while the five individual ratios retain the observed variability.
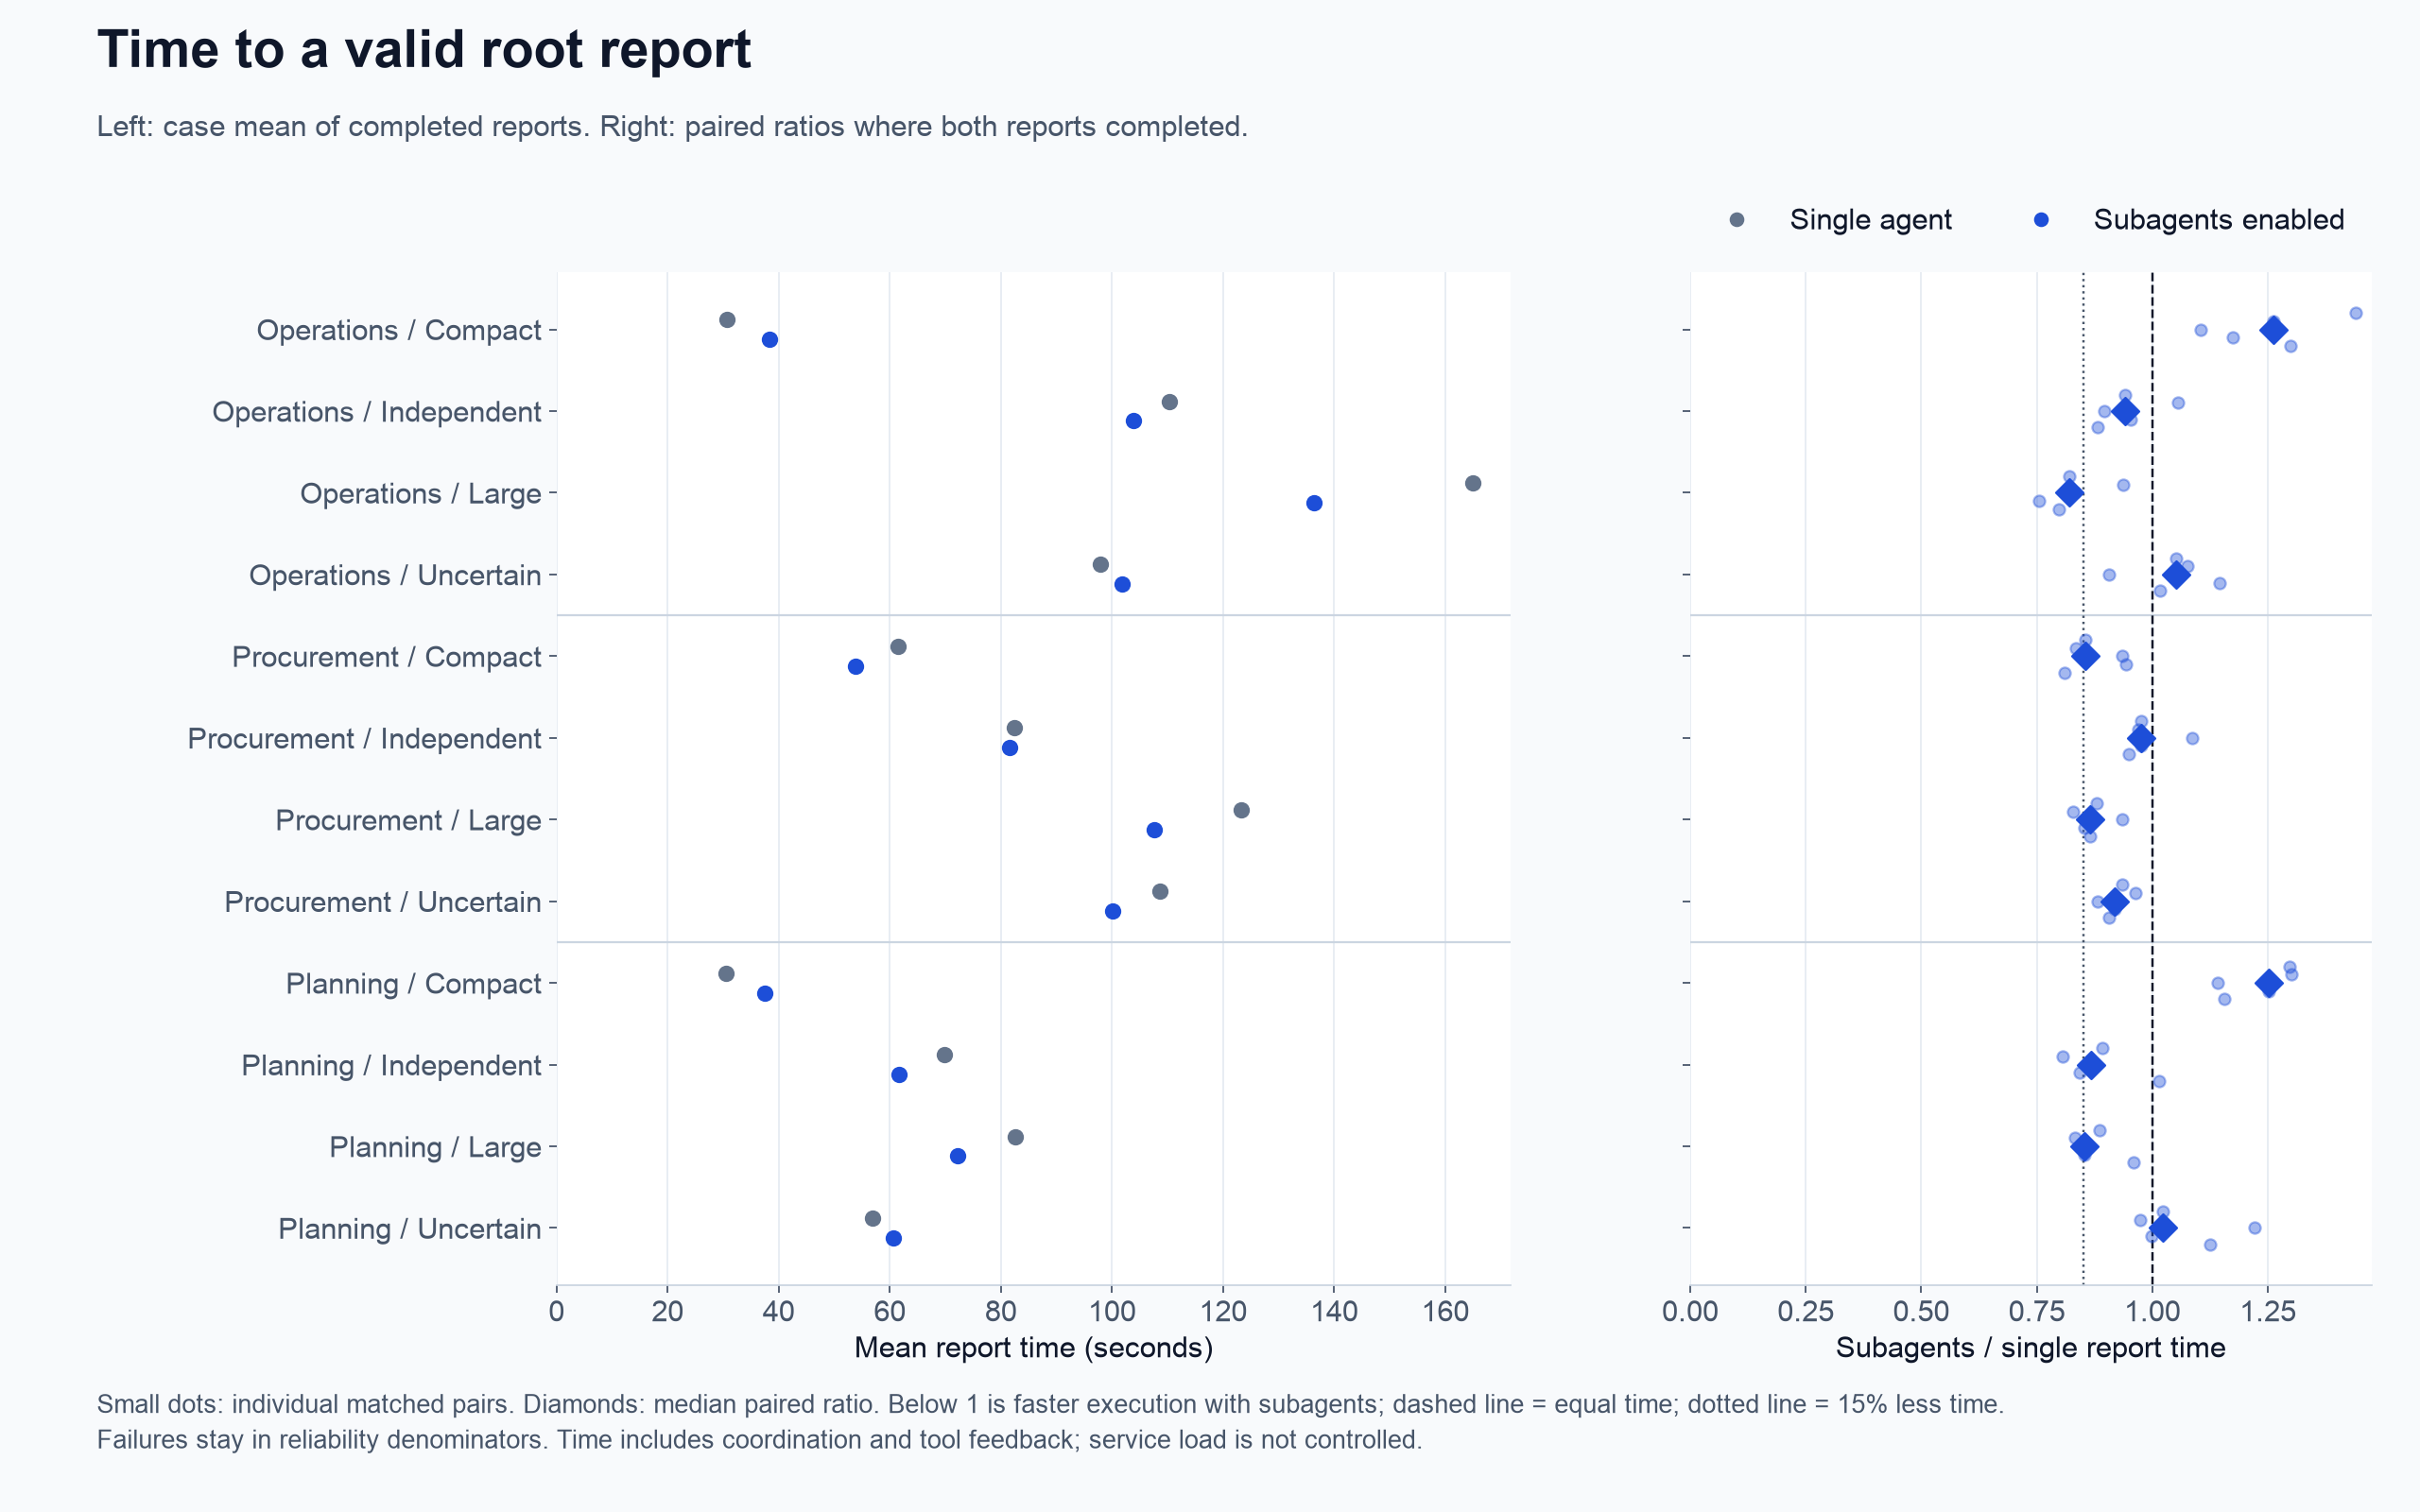
Figure 8. Case mean report times and individual paired subagents/single ratios. Diamonds show medians; a ratio below one favors execution with subagents. Only pairs with two completed reports contribute to the ratios.
The mean estimated token cost, with each case weighted equally, was approximately USD 0.065 per single-agent assessment and USD 0.112 per assessment with subagents enabled, a 71.5% increase. These estimates are based on returned token usage and have not been reconciled against invoices for the full agent tree. Figure 9 shows the same costs as USD 65.41 and USD 112.17 per 1,000 assessments. The study’s returned-token subtotal was USD 10.6548 across 120 attempts, with complete usage returned for every attempt. An assessment can contain multiple responses and developer function calls.
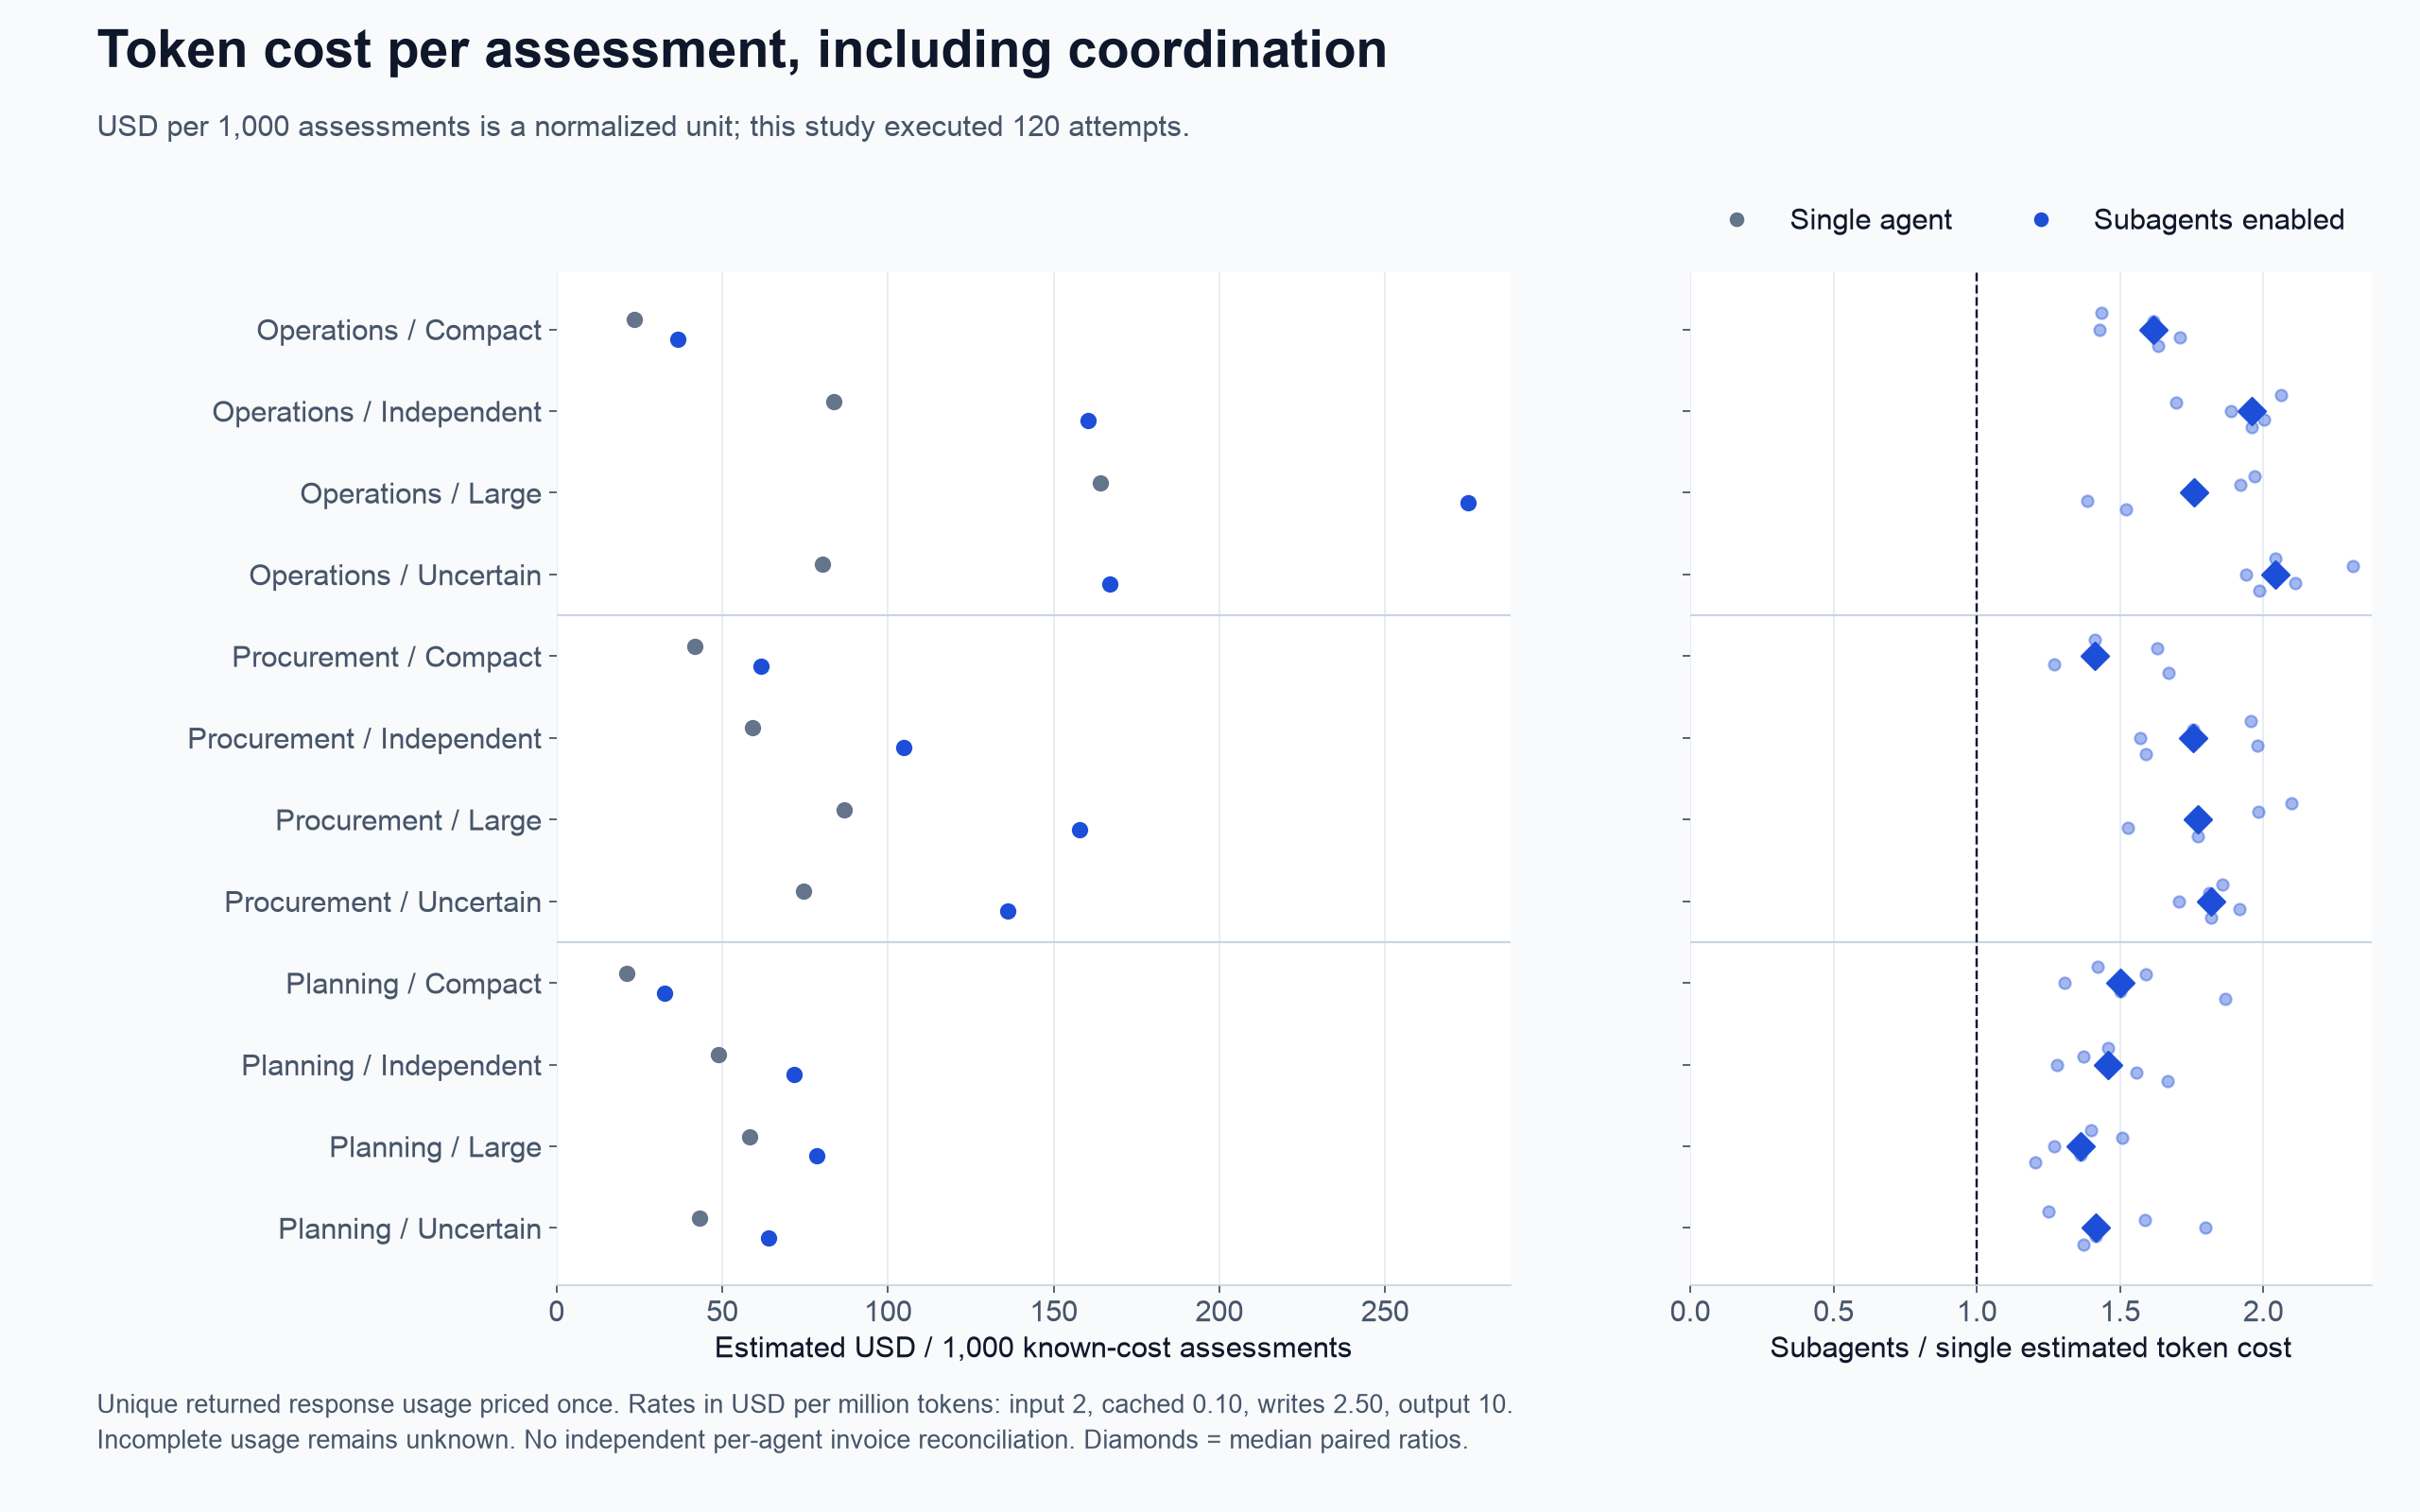
Figure 9. Estimated USD per 1,000 known-cost assessments and paired cost ratios. Costs are shown per 1,000 assessments, calculated from the recorded attempts; a single assessment may include multiple responses and tool calls.
Cost is based on each unique returned terminal response, priced once at the frozen Standard rates, which still match the model documentation: $2 per million ordinary input tokens, $0.10 per million cached input tokens, $2.50 per million cache writes, and $10 per million output tokens. All 183 unique terminal responses reported service_tier: "default"; the largest returned input count was 74,343 tokens, below the 272,000-token threshold for higher long-context rates. These estimates use Standard pricing without a regional-processing premium. Reasoning tokens are included in output, and subagent-output token estimates are not added again. Missing usage remains unknown. GPT-6.1 Sol model and pricing
Both arms requested explicit prompt-caching mode without application-supplied breakpoints. The current caching guide says that explicit mode without breakpoints does not use prompt caching or create cache writes. Nevertheless, the retained responses with subagents reported 400,056 cached input tokens across the study; single-agent responses reported none, and neither arm reported cache writes. The estimate prices these returned categories rather than inferring them from the request setting. The records do not explain the origin of those cached tokens or independently reconcile per-agent billing, so the figures are estimates from returned usage, not verified invoice totals for the full subagent tree. Prompt caching guide
The trade-offs across all twelve demo tasks
Pass counts are shown separately for each configuration. Time and cost ratios are medians over five completed pairs per task; values below 1 favor subagents.
| Case | Facts: single / subagents (%) | Single passes (of 5) | Subagent passes (of 5) | Time ratio: subagents ÷ single | Cost ratio: subagents ÷ single |
|---|---|---|---|---|---|
| Operations / Compact | 100.00/100.00 | 5 | 5 | 1.263 | 1.617 |
| Operations / Independent | 100.00/100.00 | 5 | 5 | 0.941 | 1.960 |
| Operations / Large | 85.95/100.00 | 0 | 5 | 0.821 | 1.758 |
| Operations / Uncertain | 95.86/100.00 | 1 | 5 | 1.051 | 2.043 |
| Procurement / Compact | 100.00/100.00 | 5 | 5 | 0.856 | 1.413 |
| Procurement / Independent | 100.00/100.00 | 5 | 5 | 0.975 | 1.755 |
| Procurement / Large | 99.05/100.00 | 4 | 5 | 0.865 | 1.773 |
| Procurement / Uncertain | 100.00/100.00 | 5 | 5 | 0.919 | 1.819 |
| Planning / Compact | 100.00/100.00 | 5 | 5 | 1.251 | 1.500 |
| Planning / Independent | 100.00/100.00 | 5 | 5 | 0.866 | 1.458 |
| Planning / Large | 100.00/100.00 | 5 | 5 | 0.854 | 1.363 |
| Planning / Uncertain | 100.00/100.00 | 5 | 5 | 1.023 | 1.415 |
Operations / large was the only task to meet the study’s exploratory benefit screen. Mean factual accuracy increased from 85.95% to 100%, and task passes increased from 0/5 to 5/5. The median paired time ratio indicated a 17.9% reduction, while estimated token cost increased by 75.8%. Decisions, findings, and source checks were no worse. Operations / uncertain and procurement / large also showed accuracy gains but did not meet the screen’s additional requirement of at least a 15% reduction in time or cost. This illustrative threshold is not a statistical significance test or a complete definition of value.
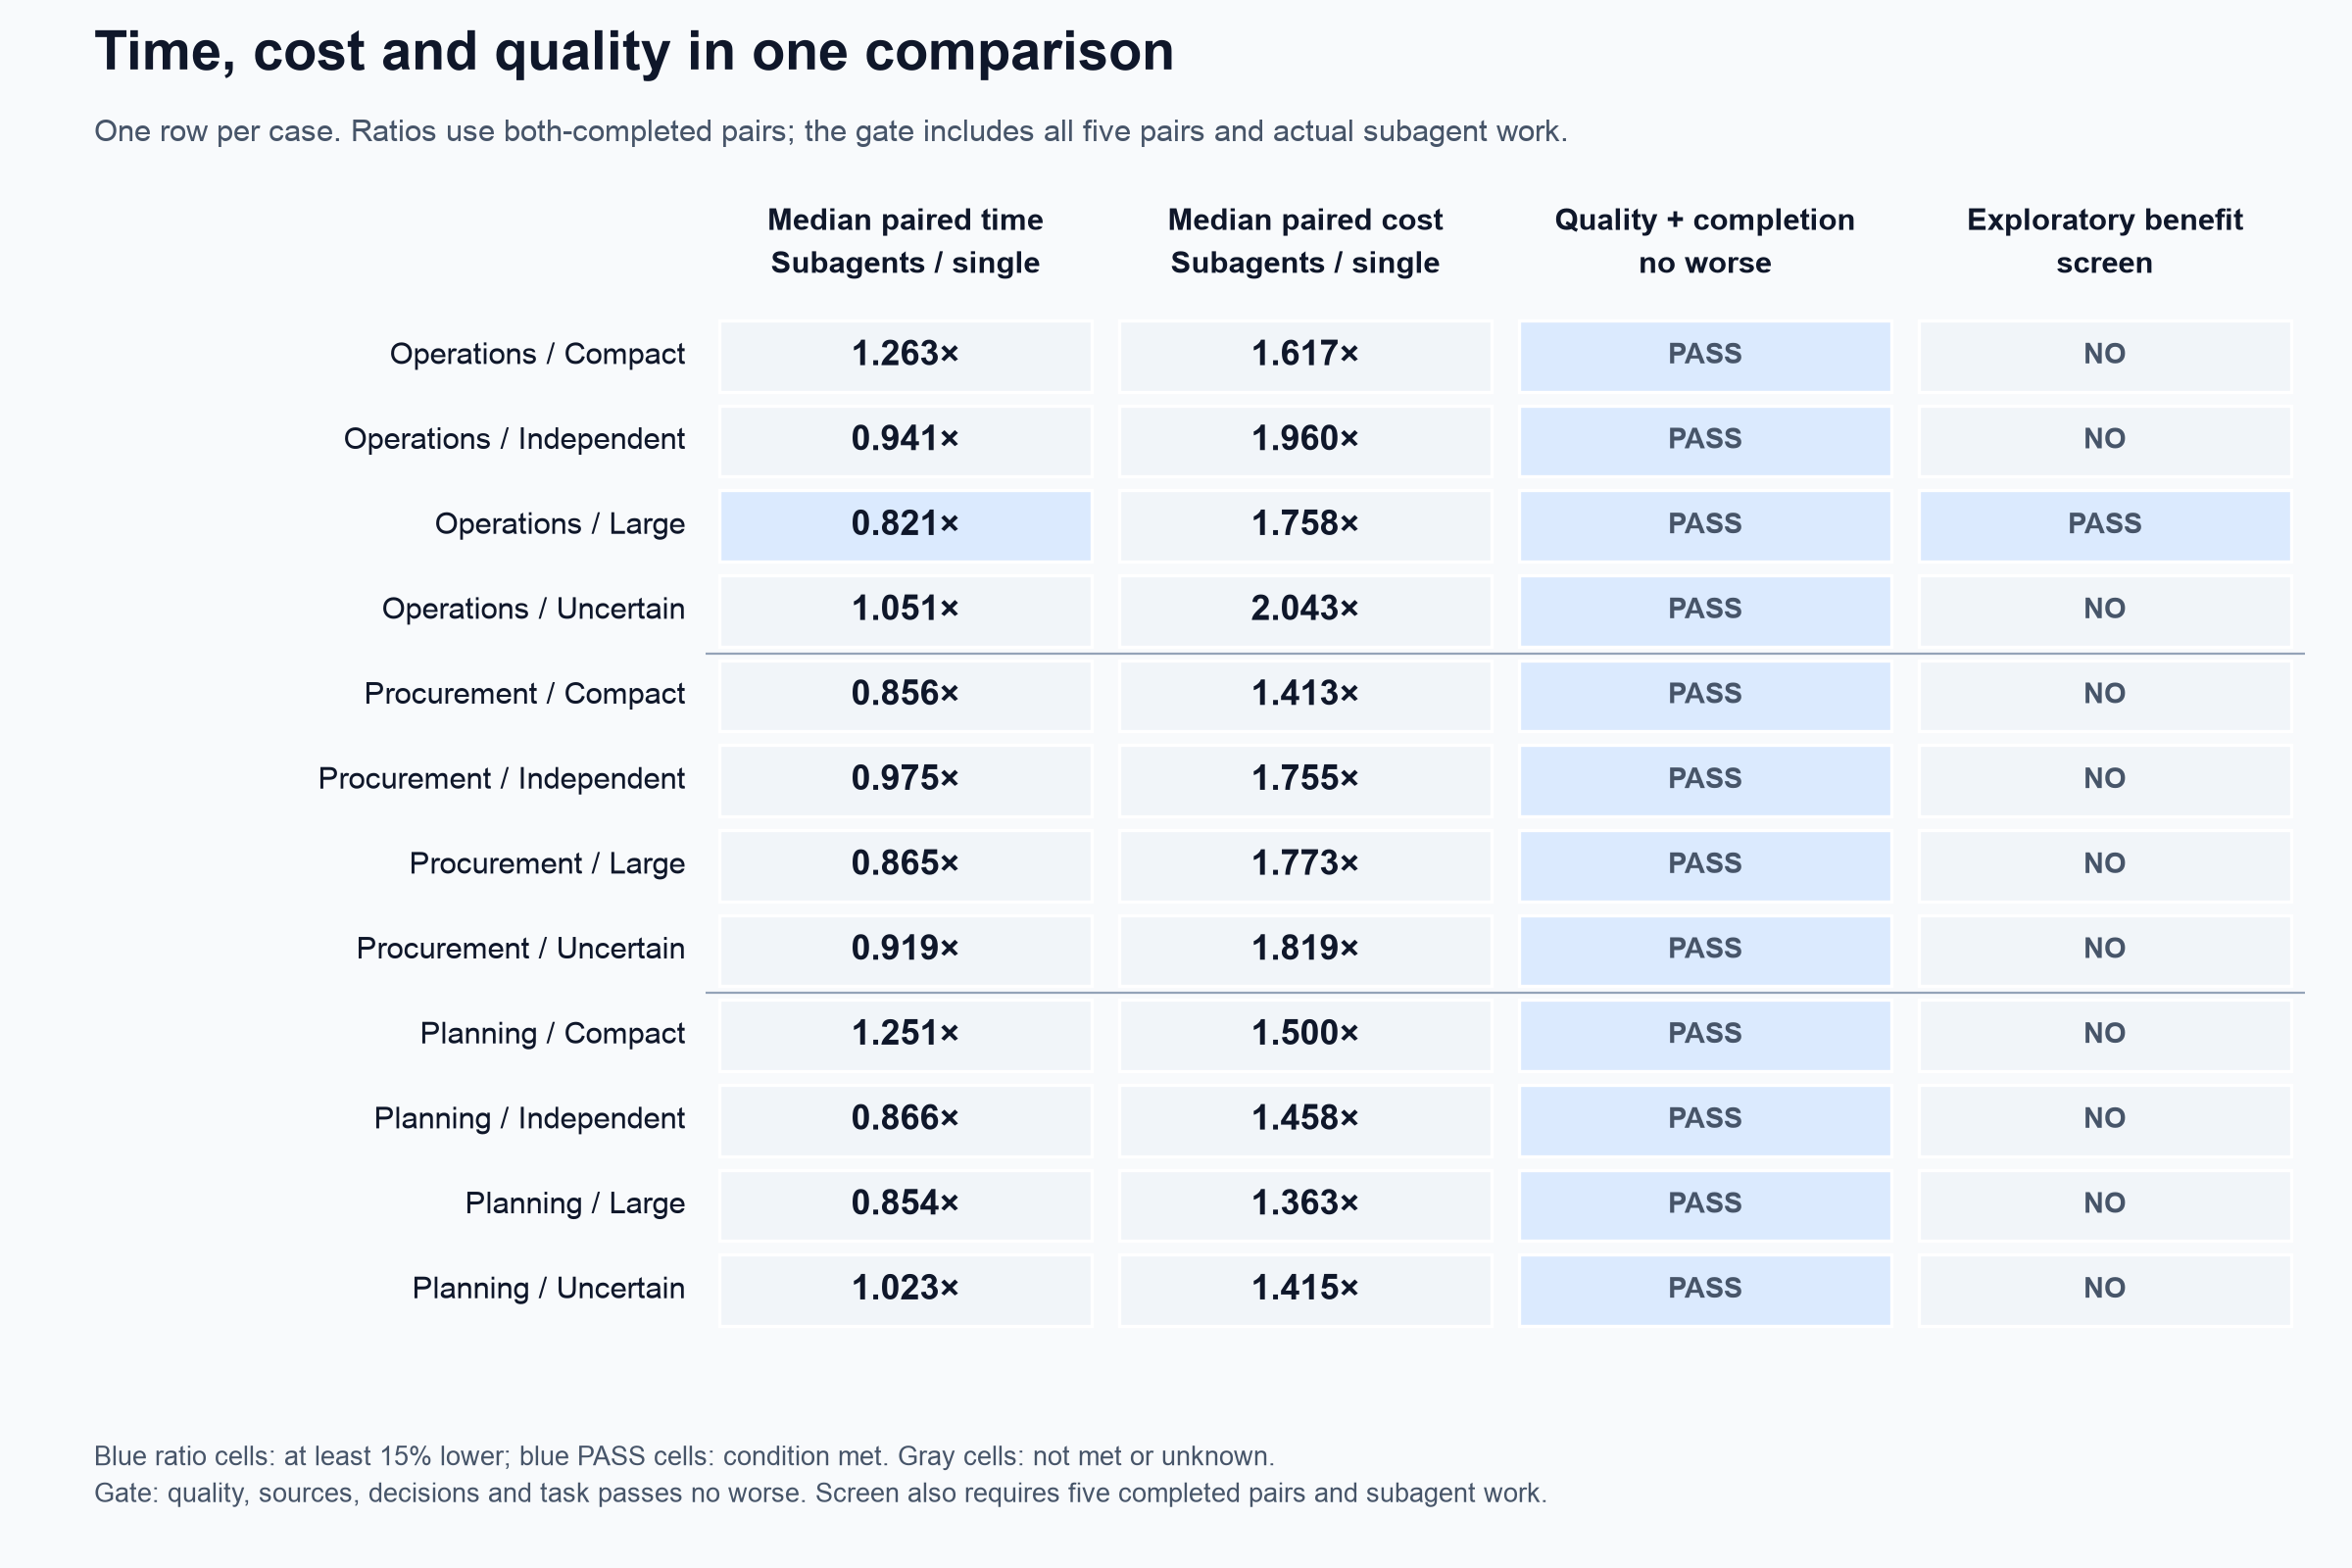
Figure 10. Paired time-and-cost ratios, the quality/completion gate, and the exploratory benefit screen using the reported task scores. Lower time or cost alone does not pass the complete screen.
What this means for GPT-6.1 Sol
For these twelve demo tasks, GPT-6.1 Sol with subagents achieved a 6.3% lower mean report time at a 71.5% higher estimated token cost. Exact factual means were 98.40% for a single agent and 100.00% with subagents, with task passes of 50/60 and 60/60, respectively. Both configurations completed every attempt, identified all expected findings, made all final decisions correctly, and met the source-dependency checks. The model used subagents in every enabled attempt. All observed subagents were direct delegates of the root, so these results do not test the value of deeper delegation.
In this suite, estimated token cost increased for every task, while factual accuracy improved in three. The independent workload profile did not consistently yield substantial time savings. These results support testing delegation against measured errors and completion time on a specific workload, rather than enabling it solely because the work can be divided.
GPT-6.1 Sol’s subagent capability gives it a way to organize independent work and verification before returning one answer. The model chooses the assignments and coordinates the team through hosted collaboration actions; the application supplies tools, constraints, and final validation. This study measured the resulting reports, completion times, returned-token costs, and execution outcomes. It did not measure development effort, maintainability, or human review time. Workloads with slow external tools or separate parts of a real codebase would extend the comparison beyond these local source packs. They would need their own matched measurements: the execution graph shows how GPT-6.1 Sol organized the work, while the root agent’s final answer shows what that organization produced.
Implementation details
The following excerpts show how the demo supports hosted delegation, returns developer-tool results, and retains the root agent’s answer. They complement the configuration overview above.
The connection and the two request modes
The endpoint, beta header, and location of multi_agent are part of the API contract, not interchangeable names for any multi-agent implementation. This study uses the Responses API beta on a generic websockets connection. Its configured developer tool is only read_evidence; subagent spawning, messaging, and waiting are hosted actions provided by the API. The following configuration excerpts come from the demo runner. They illustrate parts of the complete application: COMMON, DELEGATION, TOOL and the indexed task input are supplied by the project, and the full collector receives events and returns tool results. The connection uses a generic WebSocket library without an OpenAI or Agents SDK.
import json
from dotenv import dotenv_values
from websockets.sync.client import connect

key = dotenv_values(".env")["OPENAI_API_KEY"]
headers = {
    "Authorization": "Bearer " + key,
    "OpenAI-Beta": "responses_multi_agent=v1",
}

with connect(
    "wss://api.openai.com/v1/responses",
    additional_headers=headers,
    open_timeout=30,
    close_timeout=2,
    max_size=None,
) as socket:
    socket.send(json.dumps(
        request_body(enabled, initial_input())
    ))
    # The collector receives events and supplies
    # developer-tool results.
The request builder switches subagent availability together with its discretionary instruction paragraph. The verbatim DELEGATION string preserves the tested wording, including “native” to describe API-provided orchestration; the feature name is Multi-agent. The branch with subagents enabled sets the API’s concurrency maximum; it does not order the model to use three subagents. Depth and total-agent ceilings belong in the common instructions and client observation checks because they are not equivalent to that concurrency field. Here is the request-building logic, with the source/schema input passed in rather than an application-created subagent session:
DELEGATION = (
    "Native subagents are available. Use native subagents "
    "where useful for independent work or verification. Choose "
    "whether to delegate, how many subagents to create, their "
    "assignments, and how deeply to delegate within the "
    "resource ceilings. When delegating, give clear questions, "
    "source IDs and expected facts, findings, citations and "
    "limitations. Pass on resource constraints, wait for "
    "results, verify findings and combine them into the final "
    "answer. No agent count, division of work or delegation "
    "depth is prescribed."
)

def request_body(enabled, history, previous=None):
    body = {
        "type": "response.create",
        "model": "gpt-6.1-sol",
        "reasoning": {"effort": "medium"},
        "instructions": COMMON + (
            "\n\n" + DELEGATION if enabled else ""
        ),
        "input": history,
        "tools": [TOOL],
        "multi_agent": {"enabled": enabled},
        "store": False,
        "text": {"verbosity": "medium"},
        "max_output_tokens": 32768,
        "prompt_cache_options": {"mode": "explicit"},
        "include": ["reasoning.encrypted_content"],
    }
    if enabled:
        body["multi_agent"]["max_concurrent_subagents"] = 3
    if previous:
        body["previous_response_id"] = previous
    return body
Give the agents a shared tool contract
The demo declares one developer function, read_evidence, available to the root agent and its subagents. Its schema accepts only indexed document IDs. The local handler checks the allowlist and source hashes before returning the requested documents, ensuring consistent access for every agent. There is no developer-defined spawning function: Multi-agent supplies the hosted collaboration actions separately. This is the actual tool definition, reformatted for readability:
TOOL = {
    "type": "function",
    "name": "read_evidence",
    "description": (
        "Read immutable supplied source documents by ID from "
        "the data room index. All agents may call this tool; "
        "it cannot access grading labels or arbitrary files."
    ),
    "parameters": {
        "type": "object",
        "properties": {
            "document_ids": {
                "type": "array",
                "items": {"type": "string"},
                "minItems": 1,
                "maxItems": 36,
            }
        },
        "required": ["document_ids"],
        "additionalProperties": False,
    },
    "strict": True,
}
The schema describes the function; the application still executes it and returns its output. The handler rejects unknown IDs and arbitrary paths, and neither the schema nor the returned documents expose the private answer keys. This gives subagents the same source access as the root while keeping evaluation data outside the task context.
Tool feedback is different in the two arms
Execution with subagents can have an active root and subagents waiting for developer function results, so the collector returns a result immediately when response.output_item.done identifies a completed function call. Each result includes the matching call_id, and multi-agent injection also includes the current response_id. The single-agent response ordinarily finishes at the function-call boundary; its result must instead become input to the next response on the same socket. The following excerpt preserves that distinction and deduplicates calls by ID:
if event["type"] == "response.output_item.done":
    item = event["item"]
    if (
        item.get("type") == "function_call"
        and item["call_id"] not in seen_calls
    ):
        result = {
            "type": "function_call_output",
            "call_id": item["call_id"],
            "output": execute_tool(item),
        }
        seen_calls.add(item["call_id"])
        if enabled:
            pending_injections += 1
            socket.send(json.dumps({
                "type": "response.inject",
                "response_id": active_response_id,
                "input": [result],
            }))
        else:
            next_input.append(result)

# This continuation belongs only to the ordinary single-agent
# path.
if (
    not enabled
    and event["type"] == "response.completed"
    and next_input
):
    socket.send(json.dumps(request_body(
        False, next_input, previous=event["response"]["id"]
    )))
    next_input = []
The continuation is gated on a completed single-agent function-call response. The full collector also decrements pending injections upon acknowledgment, handles documented late-injection input via continuation, records errors, and checks deadlines. It accepts multi-agent terminal completion only after pending acknowledgments have drained, and it retains a valid root report across later responses rather than replacing it with an empty continuation. Those details matter as much as the feature flag: a transport or collection error can hide a correct answer or leave a subagent waiting even when subagent activation itself worked.
Retain the root agent’s final answer
The event stream contains contributions from several agents. A subagent’s completed message is useful working material, but the root agent owns the answer returned to the application. The collector uses attribution, completion status, and message phase to select root text before validating it against the report schema. The companion repository contains the frozen runner’s root-message filter. The single-agent path also accepts an unattributed message because ordinary responses can omit agent attribution.
The corresponding helper is available in the companion repository.
The full collector deduplicates output items and retains the latest nonempty root report that passes local validation. A later empty continuation therefore cannot erase an already completed answer. Selecting the right author and retaining valid output are separate responsibilities from enabling delegation or delivering function results.
Verifying subagent activation
The audit links hosted spawn results to work attributed to the returned subagent names. Bootstrap user messages do not count as generated work.
The corresponding helper is available in the companion repository.
Calculating estimated token cost
The per-response pricing calculation makes the units explicit. The assessment estimate is the sum over unique terminal response IDs; the per-1,000 figure is that per-assessment mean multiplied by 1,000. Input categories are disjoint, and unavailable usage is not converted into a zero-cost observation.
The corresponding helper is available in the companion repository.
Inspecting and reproducing the comparison
The distributed project contains the current WebSocket runtime, twelve demo tasks, reference calculations, scoring, and offline tests. In experiments/responses-websocket-suite-12, protocol.py defines common instructions, the read-only tool, and pricing; ws_runner.py implements the event loop; and report.py defines local output validation. grade.py checks exact values, findings, and report structure, while citation_calibration.py supplies the claim-specific source dependencies used for the reported task scores. test_citation_calibration.py checks accepted dependencies and deliberately broken citation chains. The public repository supports inspecting the implementation, running offline tests, and conducting a new paid comparison. Recreating the published figures requires the retained run artifacts, which are not included in the code-only distribution.
These offline tests require no API key and make no API calls:
python experiments/responses-websocket-suite-12/test_suite.py
python experiments/responses-websocket-suite-12/test_citation_calibration.py
The following commands regenerate the reported comparison only when the retained study results are available; they cannot recreate it from the public code-only distribution alone:
python experiments/responses-websocket-suite-12/analysis/analyze.py
python experiments/responses-websocket-suite-12/citation_calibration.py
analysis/citation-calibration/comparison.json contains the reported task scores, per-case summaries, and unchanged time and cost measurements. The same directory contains per-report source bundles and prerequisite links, as well as preservation checks for the retained run records and the grading audit. Running study.py --freeze and study.py --run would instead create a new paid study and is separate from these offline checks. Both configurations in the reported study used GPT-6.1 Sol with medium reasoning. Higher reasoning effort was not evaluated here.
Source code
The repository contains the WebSocket implementation, twelve demo tasks, output contracts, answer keys, reference calculations, deterministic graders, source-dependency checks, and offline tests, so you can inspect how GPT-6.1 Sol’s subagents are configured and compare their results with a single agent on your own tasks.
https://github.com/garystafford/hierarchical-multi-agent-systems-demo-public
This blog represents my viewpoints, not those of my past or current employers. All product names, images, logos, and brands are the property of their respective owners.
About the author
- Applied AI Engineer at OpenAI. I write about building AI applications, evaluating models, and turning experiments into practical solutions, drawing on my background in cloud architecture and software engineering.
Comments
Join the discussionNo comments yet. Be the first to comment.